# starVLA
**Repository Path**: secns/starVLA
## Basic Information
- **Project Name**: starVLA
- **Description**: No description available
- **Primary Language**: Unknown
- **License**: Not specified
- **Default Branch**: starVLA_dev
- **Homepage**: None
- **GVP Project**: No
## Statistics
- **Stars**: 0
- **Forks**: 0
- **Created**: 2026-10-26
- **Last Updated**: 2026-10-26
## Categories & Tags
**Categories**: Uncategorized
**Tags**: None
## README

StarVLA: A Lego-like Codebase for Vision-Language-Action Model Developing
An open-source research platform for integrating and exploring cutting-edge technologies for generalist robots.



> **📢 Citation Update:** Our technical report is now on arXiv ([2604.05014](https://arxiv.org/abs/2604.05014)). We kindly invite you to use the [updated BibTeX](#citation) for any ongoing or future citations. If you have already cited StarVLA in a previous version of your work, we would greatly appreciate it if you could update the citation entry in your camera-ready or future revisions. Thank you for your understanding and support! 🙏
---
In StarVLA (also a pun on "start VLA" ), each functional component (model, data, trainer, config, evaluation, etc.) follows a top-down, intuitive separation and high-cohesion, low-coupling principle, enabling plug-and-play design, rapid prototyping, and independent debugging.
## Our Team's Work
Explore our research
StarVLA is a powerful and flexible codebase for robotics research. It is also an official implementation of the following work:
- **StarVLA: A Lego-like Codebase for Vision-Language-Action Model Developing**
[ Codebase & Infrastructure ] [ StarVLA ] - [ [Paper](https://arxiv.org/abs/2604.05014) ] [ [Project](https://starvla.github.io/) ] [ [Code](https://github.com/starVLA/starVLA) ] [ [Bib](#citation) ]
- **StarVLA-α: Reducing Complexity in Vision-Language-Action Systems**
[ Evaluation ] [ StarVLA-α ] - [ [Paper](https://arxiv.org/abs/2604.11757) ] [ [Code](https://github.com/starVLA/starVLA-alpha) ] [ [Bib](#citation) ]
- **Beyond Data Scaling: Representation-Centric Continued Pre-training for Vision-Language-Action Models**
[ Pre-training ] [ VLAct ] - [ [Paper](https://arxiv.org/abs/2608.27550) ] [ [Project](https://starvla.github.io/VLAct/) ] [ [Code](https://github.com/starVLA/VLAct) ] [ [Models](https://huggingface.co/collections/StarVLA/vlact-6a903c2e0c176179da425c96) ] [ [Bib](#citation) ]
## News
> **⚠️ Branch notice:** The `starVLA_dev` branch is where we actively merge new features and may be temporarily unstable. For verified results, use the stable `starVLA` branch. Thanks to StarVLA's low-coupling design, switching between branches is painless. We encourage trying `starVLA_dev` and welcome PRs if you spot any issues!
> **💡 Tip:** Files under any `**/bar/` directory are git-ignored, so you can place your custom scripts there (e.g., `examples/simBenchmarks/LIBERO/train_files/bar/my_train.sh`) without polluting the repo.
**[2026/09/05]** 🏠 We have updated the [RoboCasa365 (PandaOmron) integration](examples/simBenchmarks/Robocasa_365) with a consolidated data, training, and evaluation guide and a 50-task local research snapshot covering StarVLA-OFT, StarVLA-PI, and StarVLA-GR00T. The best selected local result is **StarVLA-PI at 40.64% (1,016/2,500)**. These target-task/target-kitchen results are provided for research reference and are not official RoboCasa leaderboard submissions.
**[2026/08/27]** 🚀 We released **[VLAct](https://starvla.github.io/VLAct/)** and its paper, [*Beyond Data Scaling: Representation-Centric Continued Pre-training for Vision-Language-Action Models*](https://arxiv.org/abs/2608.27550). VLAct introduces representation-centric continued pre-training for reusable VLA backbones; the [code](https://github.com/starVLA/VLAct) and [models](https://huggingface.co/collections/StarVLA/vlact-6a903c2e0c176179da425c96) are now public. If you already use a Qwen3-VL-4B StarVLA recipe, set `framework.qwenvl.base_vlm` to [`StarVLA/VLAct_Qwen3_Pretrain`](https://huggingface.co/StarVLA/VLAct_Qwen3_Pretrain) to try the VLAct-pretrained backbone directly.
**[2026/08/09]** 🤖 StarVLA now supports [RoboDojo through XPolicyLab](examples/simBenchmarks/RoboDojo). The example provides training recipes for the official RoboDojo dataset and a path-based entry point for evaluating the released checkpoints with XPolicyLab.
**[2026/06/22]** 🔥 We are creating a [StarVLA Contributors Group](https://github.com/starVLA/starVLA/issues/393) to make contributor communication easier and discuss contributor list before each release. Welcome everyone to help maintain StarVLA's open-source infrastructure together.
**[2026/05/30]** 🔥 StarVLA now supports [VLA training with **Qwen-series backbones** on **Ascend NPU**](https://github.com/starVLA/starVLA/pull/336). See the [related discussion](https://github.com/starVLA/starVLA/issues/341) for details and feedback.
**[2026/04/09]** 🚀 unified **multi-benchmark co-training** example (combining LIBERO, SimplerEnv, RoboTwin, VLA-Arena, etc.) is coming soon. Stay tuned!
**[2026/05/01]** 🔥 We now provide a step-by-step guide for [integrating your own robot / dataset into StarVLA](docs/integrate_your_dataset.md).
**[2026/05/01]** 🔥 We are building [agent skills](docs/agent_skills) to make StarVLA a powerful substrate for AI coding agents — we have verified that GitHub Copilot (Claude Opus 4.7) can autonomously integrate [examples/Robocasa_365](examples/simBenchmarks/Robocasa_365) and [examples/RoboChallenge_table30v2](examples/realRobots/RoboChallenge_table30v2) from scratch. Going forward, StarVLA will be continuously optimised to be equally easy to use for humans and code agents.
**[2026/05/01]** 🙏 Special thanks to the [AllenAI](https://github.com/allenai) team for providing optimised Docker environments and evaluation-acceleration support via [vla-evaluation-harness](https://github.com/allenai/vla-evaluation-harness)! If you need to speed up large-scale VLA benchmark evaluation, we recommend checking it out.
**[2026/04/18]** 🔥 StarVLA now supports [DOMINO](examples/simBenchmarks/DOMINO), a dynamic manipulation benchmark for moving objects and time-varying scenes. Original DOMINO repository is [here](https://github.com/H-EmbodVis/DOMINO).
**[2026/04/09]** 🎯 Thanks to the [RLinf](https://rlinf.readthedocs.io) team, StarVLA now supports **RL post-training**! Check out the [StarVLA × RLinf tutorial](https://rlinf.readthedocs.io/en/latest/rst_source/examples/embodied/starvla.html) to get started.
**[2026/04/09]** 🔥 **WM4A (World Model for Action)** is now integrated! Use pretrained video-generation DiT models (Cosmos-Predict2, Wan2.2) as backbones for action prediction. See [docs/WM4A.md](docs/WM4A.md) for architecture details and training instructions. Pretrained checkpoints are available at the [StarVLA/world-model-to-vla](https://huggingface.co/collections/StarVLA/world-model-to-vla) HuggingFace collection.
**[2026/03/29]** 🔥 Thanks to the [ABot-M0](https://github.com/amap-cvlab/ABot-Manipulation) team for providing the [pre-trained weights](https://www.modelscope.cn/models/amap_cvlab/ABot-M0-Pretrain). For `Qwen3-VL 4B`, you can reload the `qwen_vl_interface` module in various frameworks!
**[2026/03/19]** 🔥 StarVLA now provides a complete real-robot development case with [Franka robot examples](https://github.com/starVLA/starVLA/pull/198)!
**[2026/03/03]** 🔥 We now support [**Qwen3.5** as a backbone for VLA](https://github.com/starVLA/starVLA/pull/172) — the fastest integration in the community ⚡
With more model size options: **0.8B, 2B, 4B, and 9B**! Build your VLA flexibly on top of native multimodal models!
**[2026/01/29]** 🔥 StarVLA [Training Efficiency Report](https://github.com/starVLA/starVLA/issues/158) & [Training Curves](https://github.com/starVLA/starVLA/issues/68) released!
Training configs and efficiency benchmarks for community reference.
**[2026/01/29]** Calvin benchmark experiments were conducted by the UNT team. For inquiries, please contact Zhijie Song (1600013008@pku.edu.cn) or Feng Yan (bphengyan@163.com).
**[2025/12/25]** We've simultaneously established pipelines for [Behavior-1K](examples/simBenchmarks/Behavior), [RoboTwin 2.0](examples/simBenchmarks/Robotwin), and CALVIN. We'd love to collaborate and share baseline results for more benchmarks with the community!
Prior Timeline
**[2025/12/25]** We've released RoboCasa evaluation support, which was trained **without pretraining and reached SOTA performance**. Check out more details in [examples/Robocasa_tabletop](examples/simBenchmarks/Robocasa_tabletop).
**[2025/12/15]** Completed a release regression check to ensure the public code runs smoothly. Routine updates—including recent support for the LeRobot dataset v3.0 and DeepSpeed ZeRO-3—will continue to appear in the [🚧 Daily Development Log](https://github.com/starVLA/starVLA/issues/64#issue-3727060165).
**[2025/12/09]** Became the first open-source repository to support training with [train your vlm](starVLA/training/train_starvlm.py), [train your vla](starVLA/training/train_starvla.py), and [train your vla with vlm](starVLA/training/train_starvla_cotrain.py). Check out how to co-train your VLA with multimodal data in [examples/CoTrainVLM](examples/modelExtensions/CoTrainVLM/README.md).
**[2025/11/12]** We now support [Florence-2](https://github.com/anyantudre/Florence-2-Vision-Language-Model) as a smaller VLM for resource-constrained development. StarVLA can now run on a single A100 GPU. See the [🚀Train with a smaller VLM](docs/faq.md#how-to-train-with-a-smaller-vlm) section for more details.
**[2025/10/30]:** We released the LIBERO Training & Evaluation README. Results are very promising. More details are in [examples/LIBERO](examples/simBenchmarks/LIBERO).
**[2025/10/25]:** We fixed several script links and so everything is smoother now. Thanks to the community for the feedback.
## Overview and Key Features

*Overview of the StarVLA framework. StarVLA organises VLA research as a
composable stack: a shared training infrastructure, pluggable foundation-model
backbones (VLM / world model), interchangeable action heads (FAST, OFT,
flow-matching π, GR00T-style dual-system), and benchmark-agnostic deployment
hooks. Each axis is decoupled, so a new framework variant typically reduces
to swapping the backbone or the action head while reusing the rest.*
Data flow diagram (click to expand)

*Data flow view of StarVLA. A unified, modular pipeline connects heterogeneous
data sources, pluggable dataloaders, and flexible data representations through
a standardised model-forwarding interface, enabling end-to-end training and
deployment.*
Various VLA Frameworks
All variants share the same data interface and infrastructure; only the action head differs.
- [x] **StarVLA-FAST**: Autoregressive discrete action tokens via a fast tokenizer (à la π₀-fast).
- [x] **StarVLA-OFT**: Parallel continuous action decoding with an MLP head (à la OpenVLA-OFT/EO).
- [x] **StarVLA-PI**: Flow-Matching action expert for diffusion-based continuous actions (à la π₀).
- [x] **StarVLA-GR00T**: Dual-system architecture — VLM as System 2, Flow-Matching as System 1 (à la GR00T).

Various Training Recipes
Every recipe is paradigm-agnostic and applies uniformly to all supported frameworks.
- [x] Supervised fine-tuning (SFT)
- [x] Multimodal Multi-objectives Co-Training
- [x] Cross-embodiment Co-Training
- [ ] Reinforcement Learning Adaptation
Broad Benchmark Integration
Achieve **state-of-the-art (SOTA) performance** on a variety of benchmarks, as follows:
- [x] **SimplerEnV**
- [x] **LIBERO**
- [x] **LIBERO-plus**
- [x] **Robocasa-GR1**
- [x] **Robocasa365**
- [x] **RoboTwin 2.0**
- [x] **DOMINO**
- [x] **BEHAVIOR**
- [x] **Calvin**
- [x] **RoboDojo**
- [ ] **SO101**
- [ ] **RLBench**
---
## 🎒 Quick Start
> **📖 New to StarVLA?** Check out our step-by-step [**Quick Start Guide**](docs/starVLA_guideline.md) — a complete walkthrough from installation to training to evaluation using the LIBERO benchmark.
---
## Benchmark Results
Results on LIBERO

Results on SimplerEnv

Results on RoboCasa GR1

Results on Calvin_D_D

We have more results for RoboCasa, RoboTwin 2.0, Behavior-1k, Calvin. See our [🍀 Overleaf](https://www.overleaf.com/read/qqtwrnprctkf#d5bdce), which continuously presents our real-time experimental results.
---
## Model Zoo
See the full list of released models and checkpoints in [docs/model_zoo.md](docs/model_zoo.md).
---
## Start Building Your VLA Like Lego!
👇 StarVLA achieves "Lego-like" development via the following designs:
1. Smoke test any submodule
StarVLA emphasizes a modular model design. Each major framework file can be run standalone for rapid debugging and smoke-testing your code. For example:
```bash
# model
python starVLA/model/framework/VLM4A/QwenOFT.py --config_yaml starvla_cotrain_oxe.yaml
# dataloader
python starVLA/dataloader/lerobot_datasets.py --config_yaml starvla_cotrain_oxe.yaml
```
Note: `starVLA/model/framework/VLM4A/yourframework.py` is the single external API surface of the model; it should mirror (be structurally isomorphic to) the framework diagram in your paper.
2. Explicit model boundaries
StarVLA follows top‑down decomposition and the principle of high cohesion & low coupling.
For example:
- Dataloader
- Returns a raw, model‑agnostic dict only; no model‑specific preprocessing (e.g., tokenizer, image encoding).
- A single sample should include (add/remove as needed):
- image: list[PIL.Image] | np.ndarray
- lang: str
- action: np.ndarray[T, action_dim]
- state: Optional[np.ndarray[..., state_dim]]
Both `framework.forward()` and `framework.predict_action()` operate directly on raw inputs, keeping train/test boundaries explicit and easy to hack.
3. Flexible configuration system
StarVLA uses a single global configuration object
Parameters are passed primarily via extensible dicts, allowing overrides and controlled redundancy.
---
## FAQ
See [docs/faq.md](docs/faq.md) for common questions on configuration, freezing, learning rates, checkpointing, smaller VLMs, and more.
## Contributing
Community contributors are the driving force behind StarVLA's growing ecosystem. We deeply appreciate every PR, bug fix, and piece of feedback from the open-source community — your efforts keep StarVLA evolving rapidly. A full, continuously updated contributor list is maintained at [starvla.github.io/contributors](https://starvla.github.io/contributors).
Thanks to all the people who have contributed to StarVLA:
 See [docs/CONTRIBUTING.md](docs/CONTRIBUTING.md) for guidelines on reporting bugs, proposing features, and submitting PRs.
### Projects Based on StarVLA
**NeuroVLA**: [*A Brain-like Embodied Intelligence for Fluid and Fast Reflexive Robotics Control*](https://github.com/guoweiyu/NeuroVLA)
**PhysBrain**: [*Human Egocentric Data as a Bridge from Vision Language Models to Physical Intelligence*](https://zgc-embodyai.github.io/PhysBrain)
**TwinBrainVLA**: [*TwinBrainVLA: Unleashing the Potential of Generalist VLMs for Embodied Tasks via Asymmetric Mixture-of-Transformers*](https://github.com/ZGC-EmbodyAI/TwinBrainVLA)
**LangForce** (ICML 2026): [*LangForce: Bayesian Decomposition of Vision Language Action Models via Latent Action Queries*](https://github.com/ZGC-EmbodyAI/LangForce)
**LaWAM**: [*LaWAM: Latent World Action Models for Efficient Dynamics-Aware Robot Policies*](https://github.com/RLinf/LaWAM)
Examples:
```bash
accelerate launch \
--config_file starVLA/config/deepseeds/deepspeed_zero2.yaml \
--num_processes 8 \
starVLA/training/train_internvla.py \
--config_yaml examples/simBenchmarks/SimplerEnv/train_files/starvla_cotrain_oxe.yaml \
--framework.qwenvl.base_vlm Qwen/Qwen2.5-VL-7B-Instruct \ # override framework choice
--framework.qwenvl.base_vlm Qwen/Qwen2.5-VL-7B-Instruct \ # override framework choice
--framework.action_model.new_module ${module_name} \ # plug-in a new module to action model
```
⚠️: `framework.action_model.new_module` only adds to the global config; its behavior is on your framework.
Q: Can I freeze the VLM via parameters?
A: Yes. StarVLA uses a regex / name list to control freezing. Example:
```
--trainer.freeze_modules "qwen_vl_interface.model.model.visual,dino_encoder" \
```
Tips: You can ``print(your_model)`` first to check the relative paths of your modules and list them as comma-separated values.
(implementation in `TrainerUtils.freeze_backbones`.)
Q: Can I set different learning rates for different modules?
A: Yes, starVLA also uses name: value dict to control learning group. Config example:
```yaml
trainer:
learning_rate:
base: 1e-05 # other modules
qwen_vl_interface: 1.0e-05
action_model: 1.0e-04
```
(Also referenced in `trainer_tools.build_param_lr_groups`.)
Q: Can I resume training from a checkpoint?
A: Yes, somehow can. Specify the latest checkpoint path in `config.yaml`, e.g.:
```yaml
trainer:
pretrained_checkpoint: path_to_steps_10000.pt
reload_modules: "action_model"
```
Empty `reload_modules` means full load all model. However, starVLA does not save `optimizer state`. It requires a lot of memory/disk and bring limited benefit.
🚀 Train with a smaller VLM
```bash
accelerate launch \
--config_file starVLA/config/deepseeds/deepspeed_zero2.yaml \
--main_process_ip $MASTER_ADDR \
--main_process_port $MASTER_PORT \
--machine_rank $SLURM_PROCID \
--num_machines $SLURM_NNODES \
--num_processes=${TOTAL_GPUS} \
starVLA/training/train_starvla.py \
--config_yaml examples/simBenchmarks/SimplerEnv/train_files/starvla_cotrain_oxe.yaml \
--framework.name QwenGR00T \
--framework.qwenvl.base_vlm microsoft/Florence-2-large \
--run_root_dir ${run_root_dir} \
--run_id ${run_id} \
--wandb_project your_project \
--wandb_entity your_name
```
Note: To ensure better compatibility with already released checkpoints, we are continuing to use `--framework.qwenvl`. This parameter will be unified in the next release.
## ✍️ Citation & Copyright
StarVLA is released under the MIT License, which permits commercial use, modification, distribution, and private use. Rebases are allowed for forks and feature branches; when rebasing from upstream StarVLA, use descriptive commit messages (e.g., "chore: rebase from StarVLA") and keep at least the two latest upstream commits as separate. See [License](LICENSE) for details.
```bibtex
@article{yang2026beyond,
title={Beyond Data Scaling: Representation-Centric Continued Pre-training for Vision-Language-Action Models},
author={Yang, Senqiao and Wang, Chengyao and Chen, Yuxin and Wang, Zixuan and Tang, Longxiang and Gui, Haokun and Ye, Jinhui and Lu, Changsheng and Wu, Xiaoyang and Zhu, Mingkang and others},
journal={arXiv preprint arXiv:2608.27550},
year={2026}
}
@inproceedings{ye2026starvla,
title={StarVLA-$$\backslash$alpha $: Reducing Complexity in Vision-Language-Action Systems},
author={Ye, Jinhui and Gao, Ning and Yang, Senqiao and Zheng, Jinliang and Wang, Zixuan and Chen, Yuxin and Chen, Pengguang and Chen, Yilun and Liu, Shu and Jia, Jiaya},
booktitle = {European Conference on Computer Vision (ECCV)},
year = {2026}
}
@article{community2026starvla,
title={StarVLA: A Lego-like Codebase for Vision-Language-Action Model Developing},
author={Community, StarVLA},
journal={arXiv preprint arXiv:2604.05014},
year={2026},
eprint={2604.05014},
archivePrefix={arXiv},
primaryClass={cs.RO}
}
```
## Acknowledgements
This project draws inspiration and references from several notable open-source initiatives, including:
- [LeRobot](https://github.com/huggingface/lerobot)
- [GR00T](https://github.com/NVIDIA/Isaac-GR00T/tree/main)
- [DeepSpeed](https://github.com/deepspeedai/DeepSpeed)
- [Qwen-VL](https://github.com/QwenLM/Qwen3-VL/tree/main)
- [InternVL](https://github.com/OpenGVLab/InternVL)
- [ABot-Manipulation](https://github.com/amap-cvlab/ABot-Manipulation)
The codebase was originally forked from [InternVLA-M1](https://github.com/InternRobotics/InternVLA-M1).
## Star History
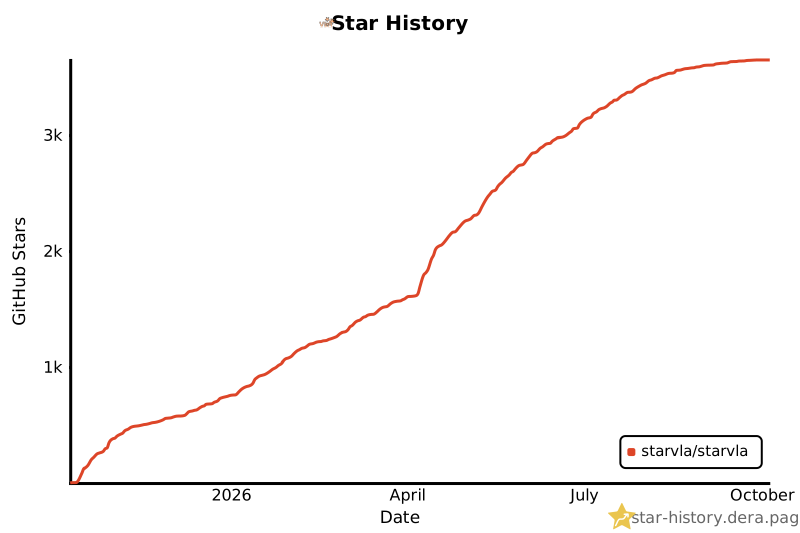
Here's how our community has grown over time:
[](https://star-history.dera.page/#starVLA/starVLA&type=date&legend=bottom-right)