# PageIndex
**Repository Path**: stonelab/PageIndex
## Basic Information
- **Project Name**: PageIndex
- **Description**: clone https://github.com/VectifyAI/PageIndex.git
- **Primary Language**: Unknown
- **License**: MIT
- **Default Branch**: main
- **Homepage**: None
- **GVP Project**: No
## Statistics
- **Stars**: 0
- **Forks**: 0
- **Created**: 2026-11-11
- **Last Updated**: 2026-11-11
## Categories & Tags
**Categories**: Uncategorized
**Tags**: None
## README
# PageIndex: Vectorless, Reasoning-based RAG
Reasoning-based RAG β¦ No Vector DB, No Chunking β¦ Context-Aware Retrieval β¦ Reads Like a Human
Updates
- [Oct '26] π₯ [**Page Search API**](https://search.pageindex.ai): find the pages that answer each question in about a second, and send your LLM only those. *Cut 97% token cost on document question answering*; more accurate and faster than vector search ([benchmark](https://github.com/VectifyAI/page-search-benchmark)).
- [Aug '26] [**PageIndex SDK**](#quickstart): **local** and **cloud** modes β one client to index, retrieve, and chat on your machine (with your own LLM API key) or on [PageIndex Cloud](https://developer.pageindex.ai/).
- [Aug '26] β‘ [**PageIndex Flash**](https://pageindex.ai/blog/pageindex-flash): fast tree index generation for text-based PDFs, now the default indexing method in PageIndex SDK local mode.
- [Scale PageIndex to Millions of Documents](https://pageindex.ai/blog/pageindex-filesystem): *PageIndex File System* is a file-level tree indexing layer that lets PageIndex reason over an entire corpus, not just a single document.
- [PageIndex App](https://app.pageindex.ai): a human-like document analysis agent for long professional documents.
# What is PageIndex?
Are you frustrated with vector database retrieval accuracy for long and complex documents? Vector-based RAG retrieves by semantic **similarity**. But **similarity β relevance** β what retrieval actually needs is relevance, and relevance requires **reasoning**. On professional documents that demand contextual understanding, domain expertise, and multi-step reasoning, similarity search misses what is relevant but not similar, and returns what is similar but not relevant.
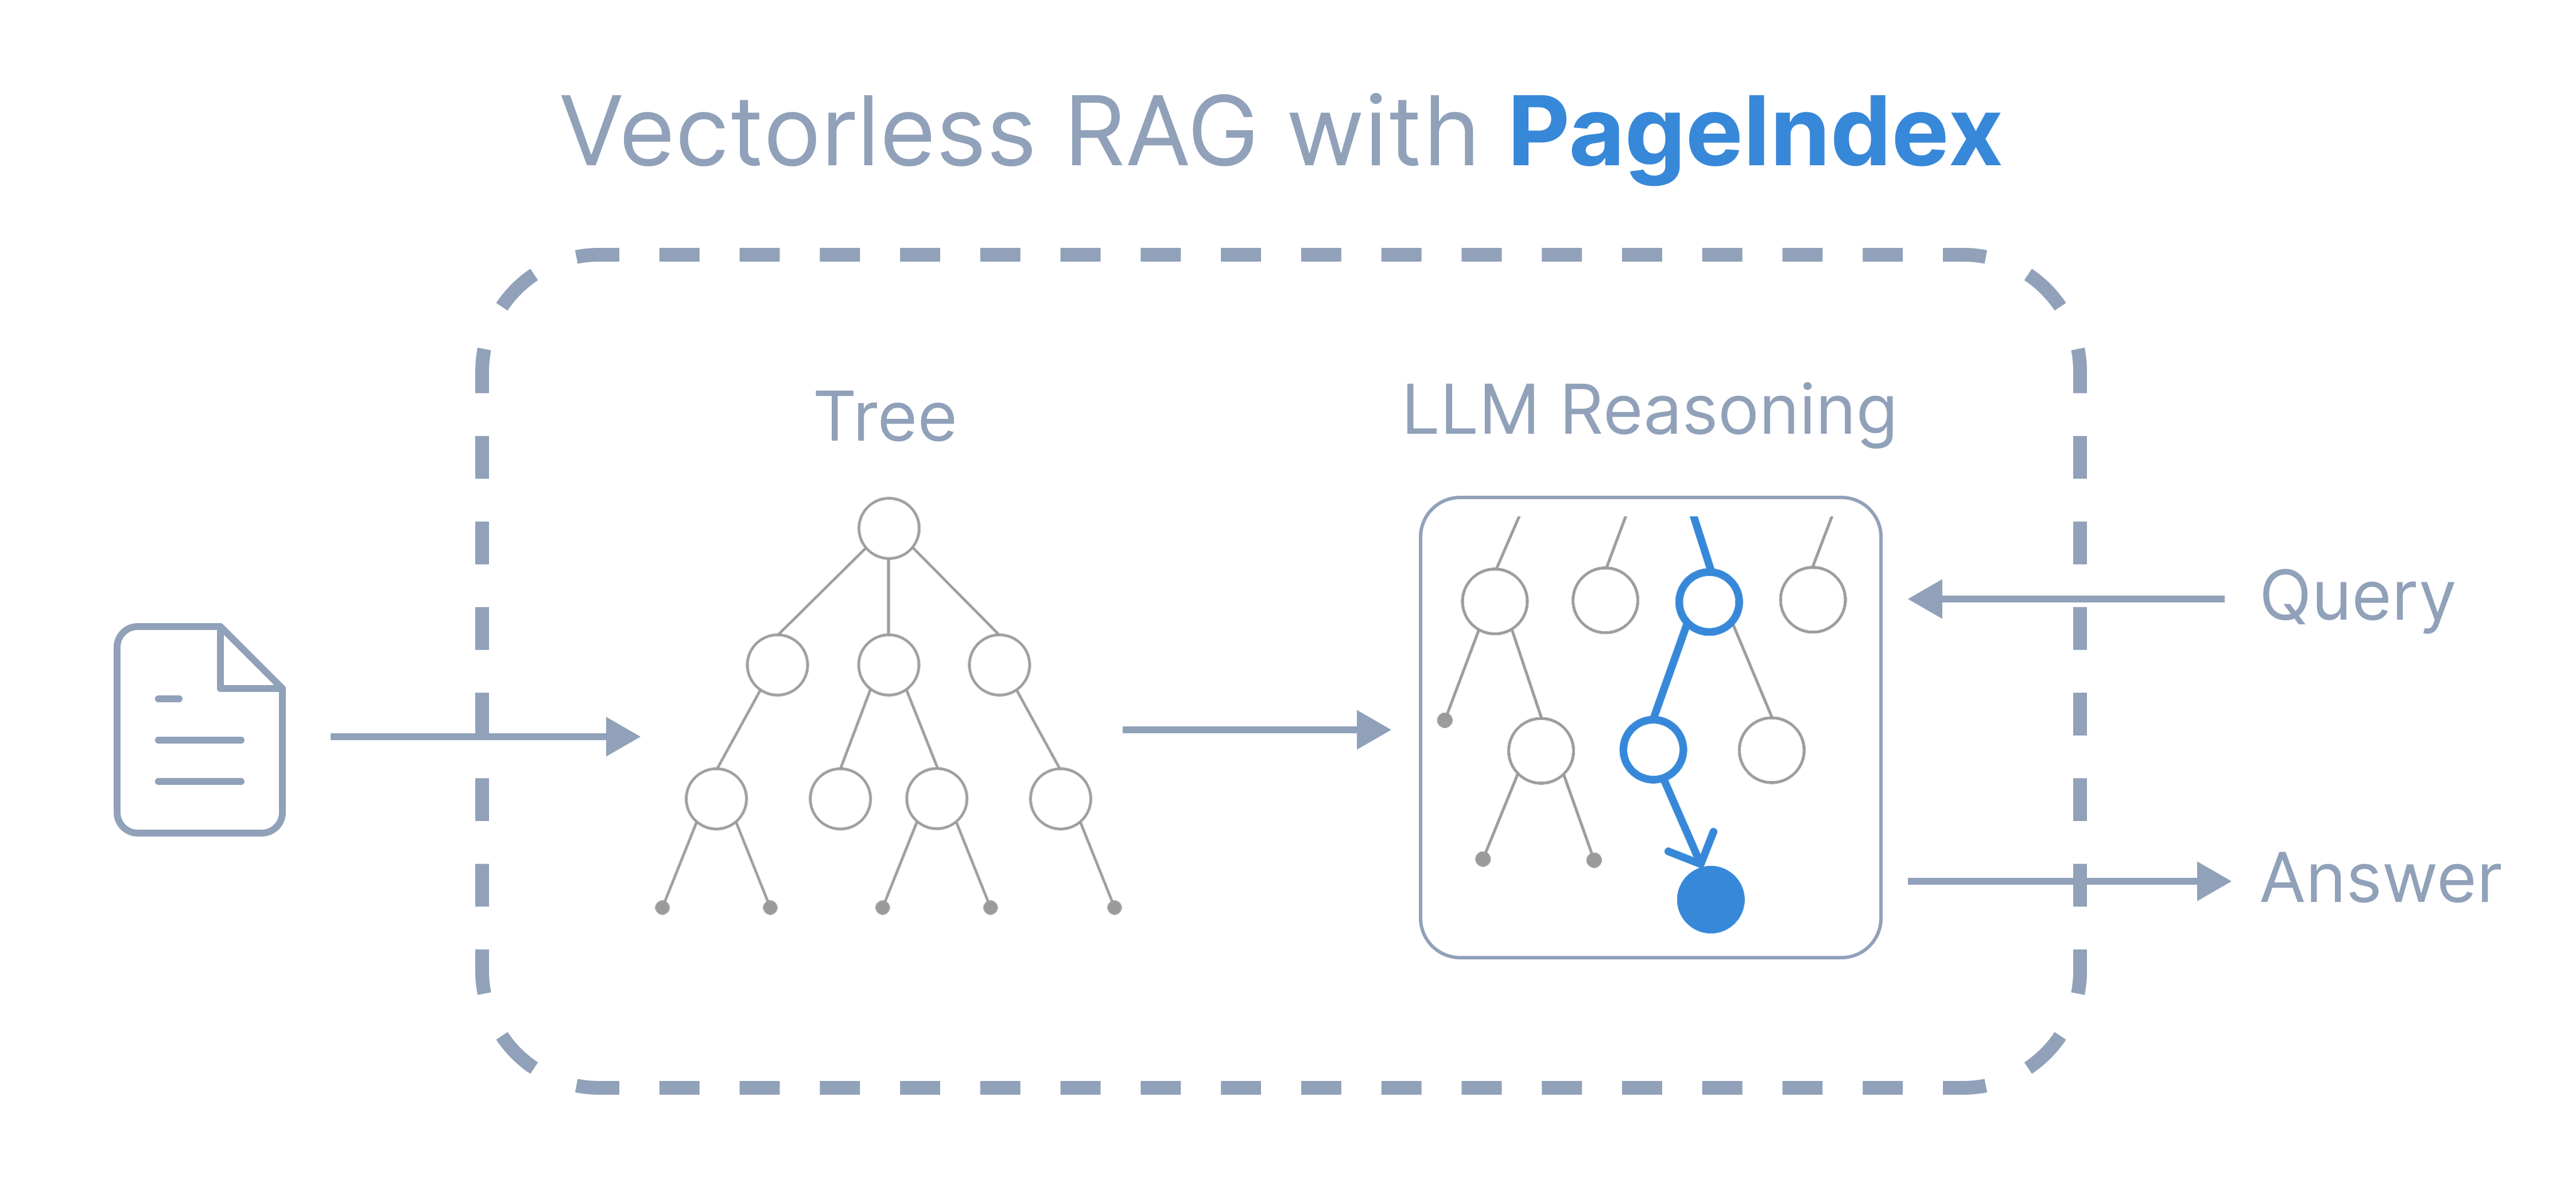
Inspired by AlphaGo, **[PageIndex](https://vectify.ai/pageindex)** replaces the vector index with a **hierarchical tree index** and lets an LLM **reason** its way through it, the way a human expert turns to and reads the right section of a long report. Retrieval happens in two steps:
1. **Index**: generate a **tree-structure index** for each document
2. **Retrieve**: agentically **search that tree** with LLM reasoning
### TL;DR
PageIndex is a vectorless, reasoning-based RAG engine that mirrors how humans read, delivering traceable, explainable, and context-aware retrieval, with no vector DBs or chunking.
### Compare with Vector RAG
| | Vector RAG | **PageIndex** |
|---|---|---|
| **Index** | vector index | tree index |
| **Retrieval** | semantic similarity search | LLM reasoning over the tree |
| **Result** | opaque, βvibe retrievalβ | traceable to explicit references |
| **Context** | query embedding only | full context: conversation history, domain knowledge, etc. |
It is ideal for financial reports, legal documents, regulatory filings, technical manuals, medical literature, academic textbooks, and any other long, complex professional document.
# Quickstart
```bash
pip install -U pageindex
```
```python
import os
from pageindex import PageIndexClient
os.environ["OPENAI_API_KEY"] = "your-openai-key"
client = PageIndexClient(
index="gpt-6-luna", # model to build the tree index
chat="gpt-6-sol", # model to search the tree
)
doc_id = client.submit_document("report.pdf")["doc_id"]
answer = client.chat("What was the 2023 operating margin?", doc_id=doc_id)
print(answer)
```
### Model Recommendations
- **`index=`: a basic model is sufficient.** The tree structure itself is extracted from the document layout without an LLM; the index model only summarizes and refines it, which a basic model does well.
- **`chat=`: use the best model you can afford.** The chat model searches the tree to retrieve information. See [Query cost and accuracy](#query-cost-and-accuracy).
**Have a Claude subscription?** PageIndex can use your subscription to call Claude models through Claude Code: usage is covered by your plan, no API key needed. Install with `pip install -U "pageindex[claude]"`, then prefix model names with `claude-code/`, e.g., `index="claude-code/haiku"`, `chat="claude-code/opus"` (see [example](https://github.com/VectifyAI/PageIndex/blob/main/cookbook/pageindex-claude-subscription.py)).
### [Use PageIndex through the SDK client β](https://docs.pageindex.ai/getting-started)
Configure other models, streaming, multi-document search, citations, and more.
### [Integrate PageIndex with your own agent β](https://docs.pageindex.ai/sdk/agents)
Drop PageIndex tools into the OpenAI Agents SDK, the Claude Agent SDK, or any other framework.
# Benchmarks
### Local indexing cost and time
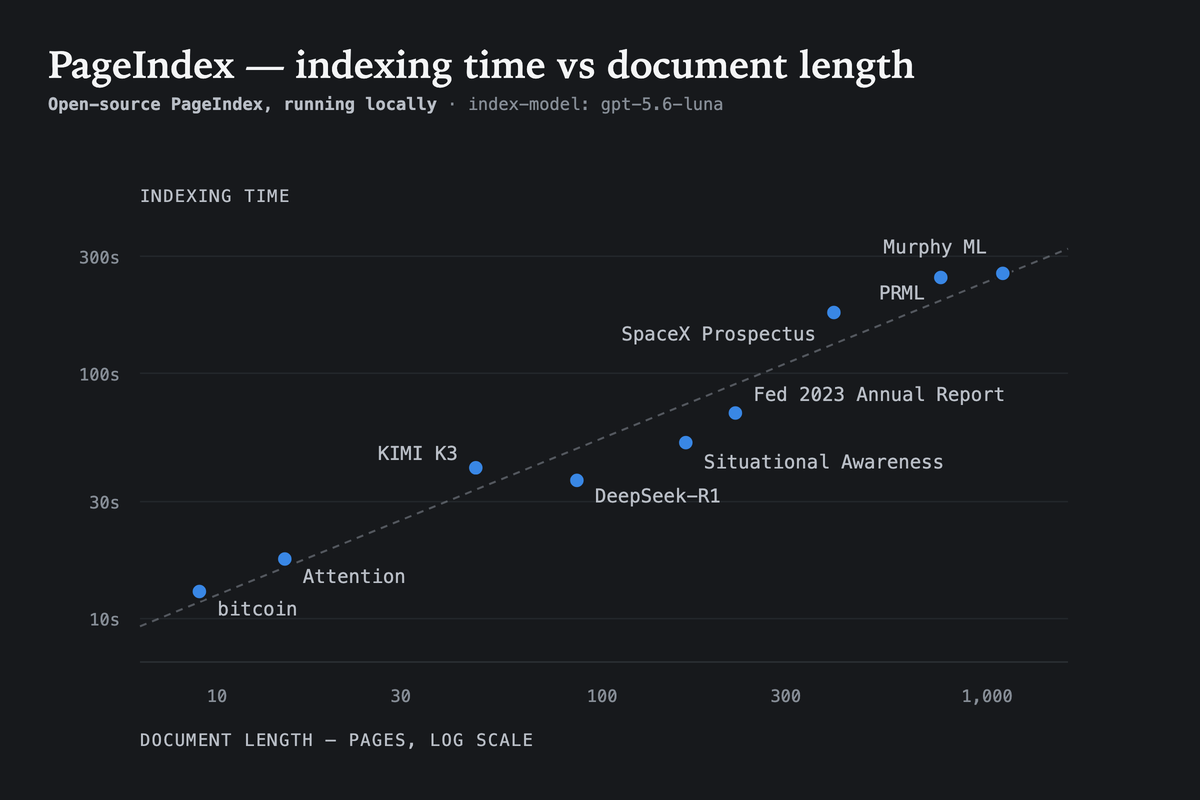
Building a tree locally runs **about $0.001 per page** with `gpt-5.6-luna` as the index model, so a 1,000-page textbook costs a little over a dollar and a few minutes, once, and every later question reuses it. PageIndex is designed not to rely heavily on the model used at index time, so in our experiments a basic model does not hurt quality.
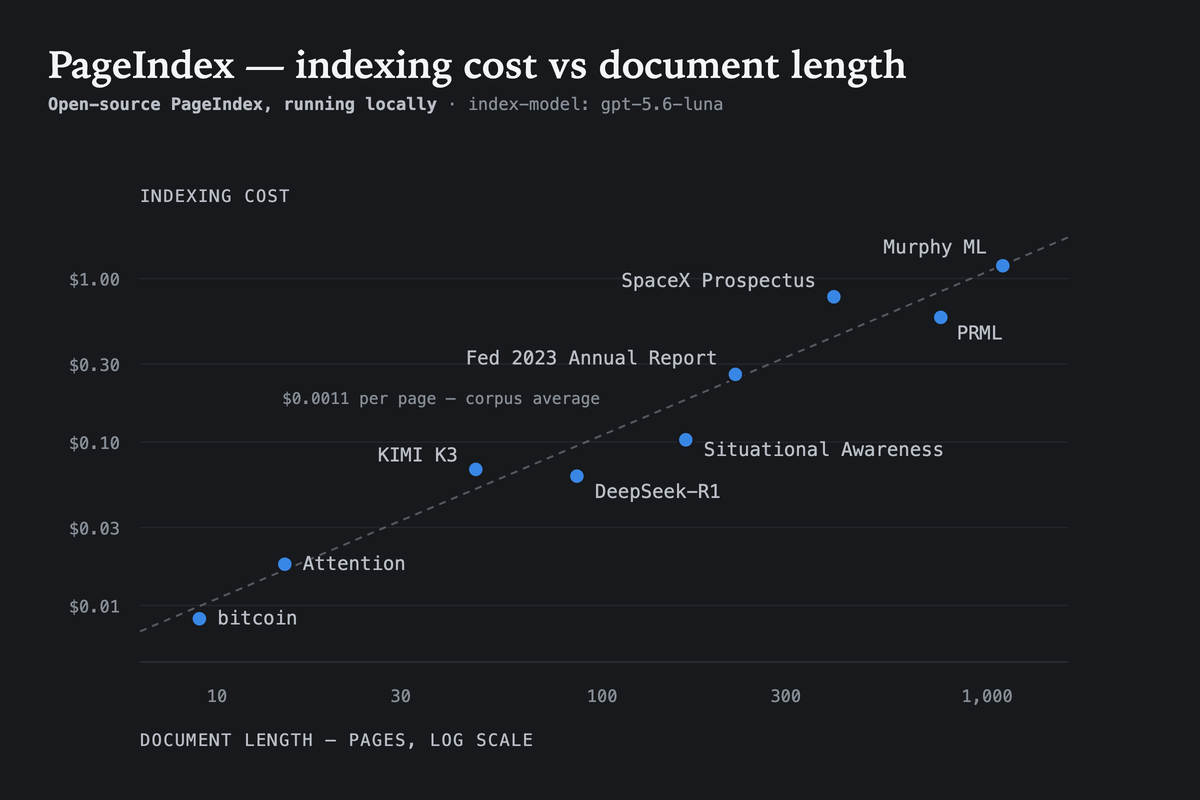
Indexing time also scales predictably with document length. In the same local setup, the benchmark documents (9 to 1,098 pages) finished in roughly **13 seconds to 4.5 minutes**.
### Query cost and accuracy
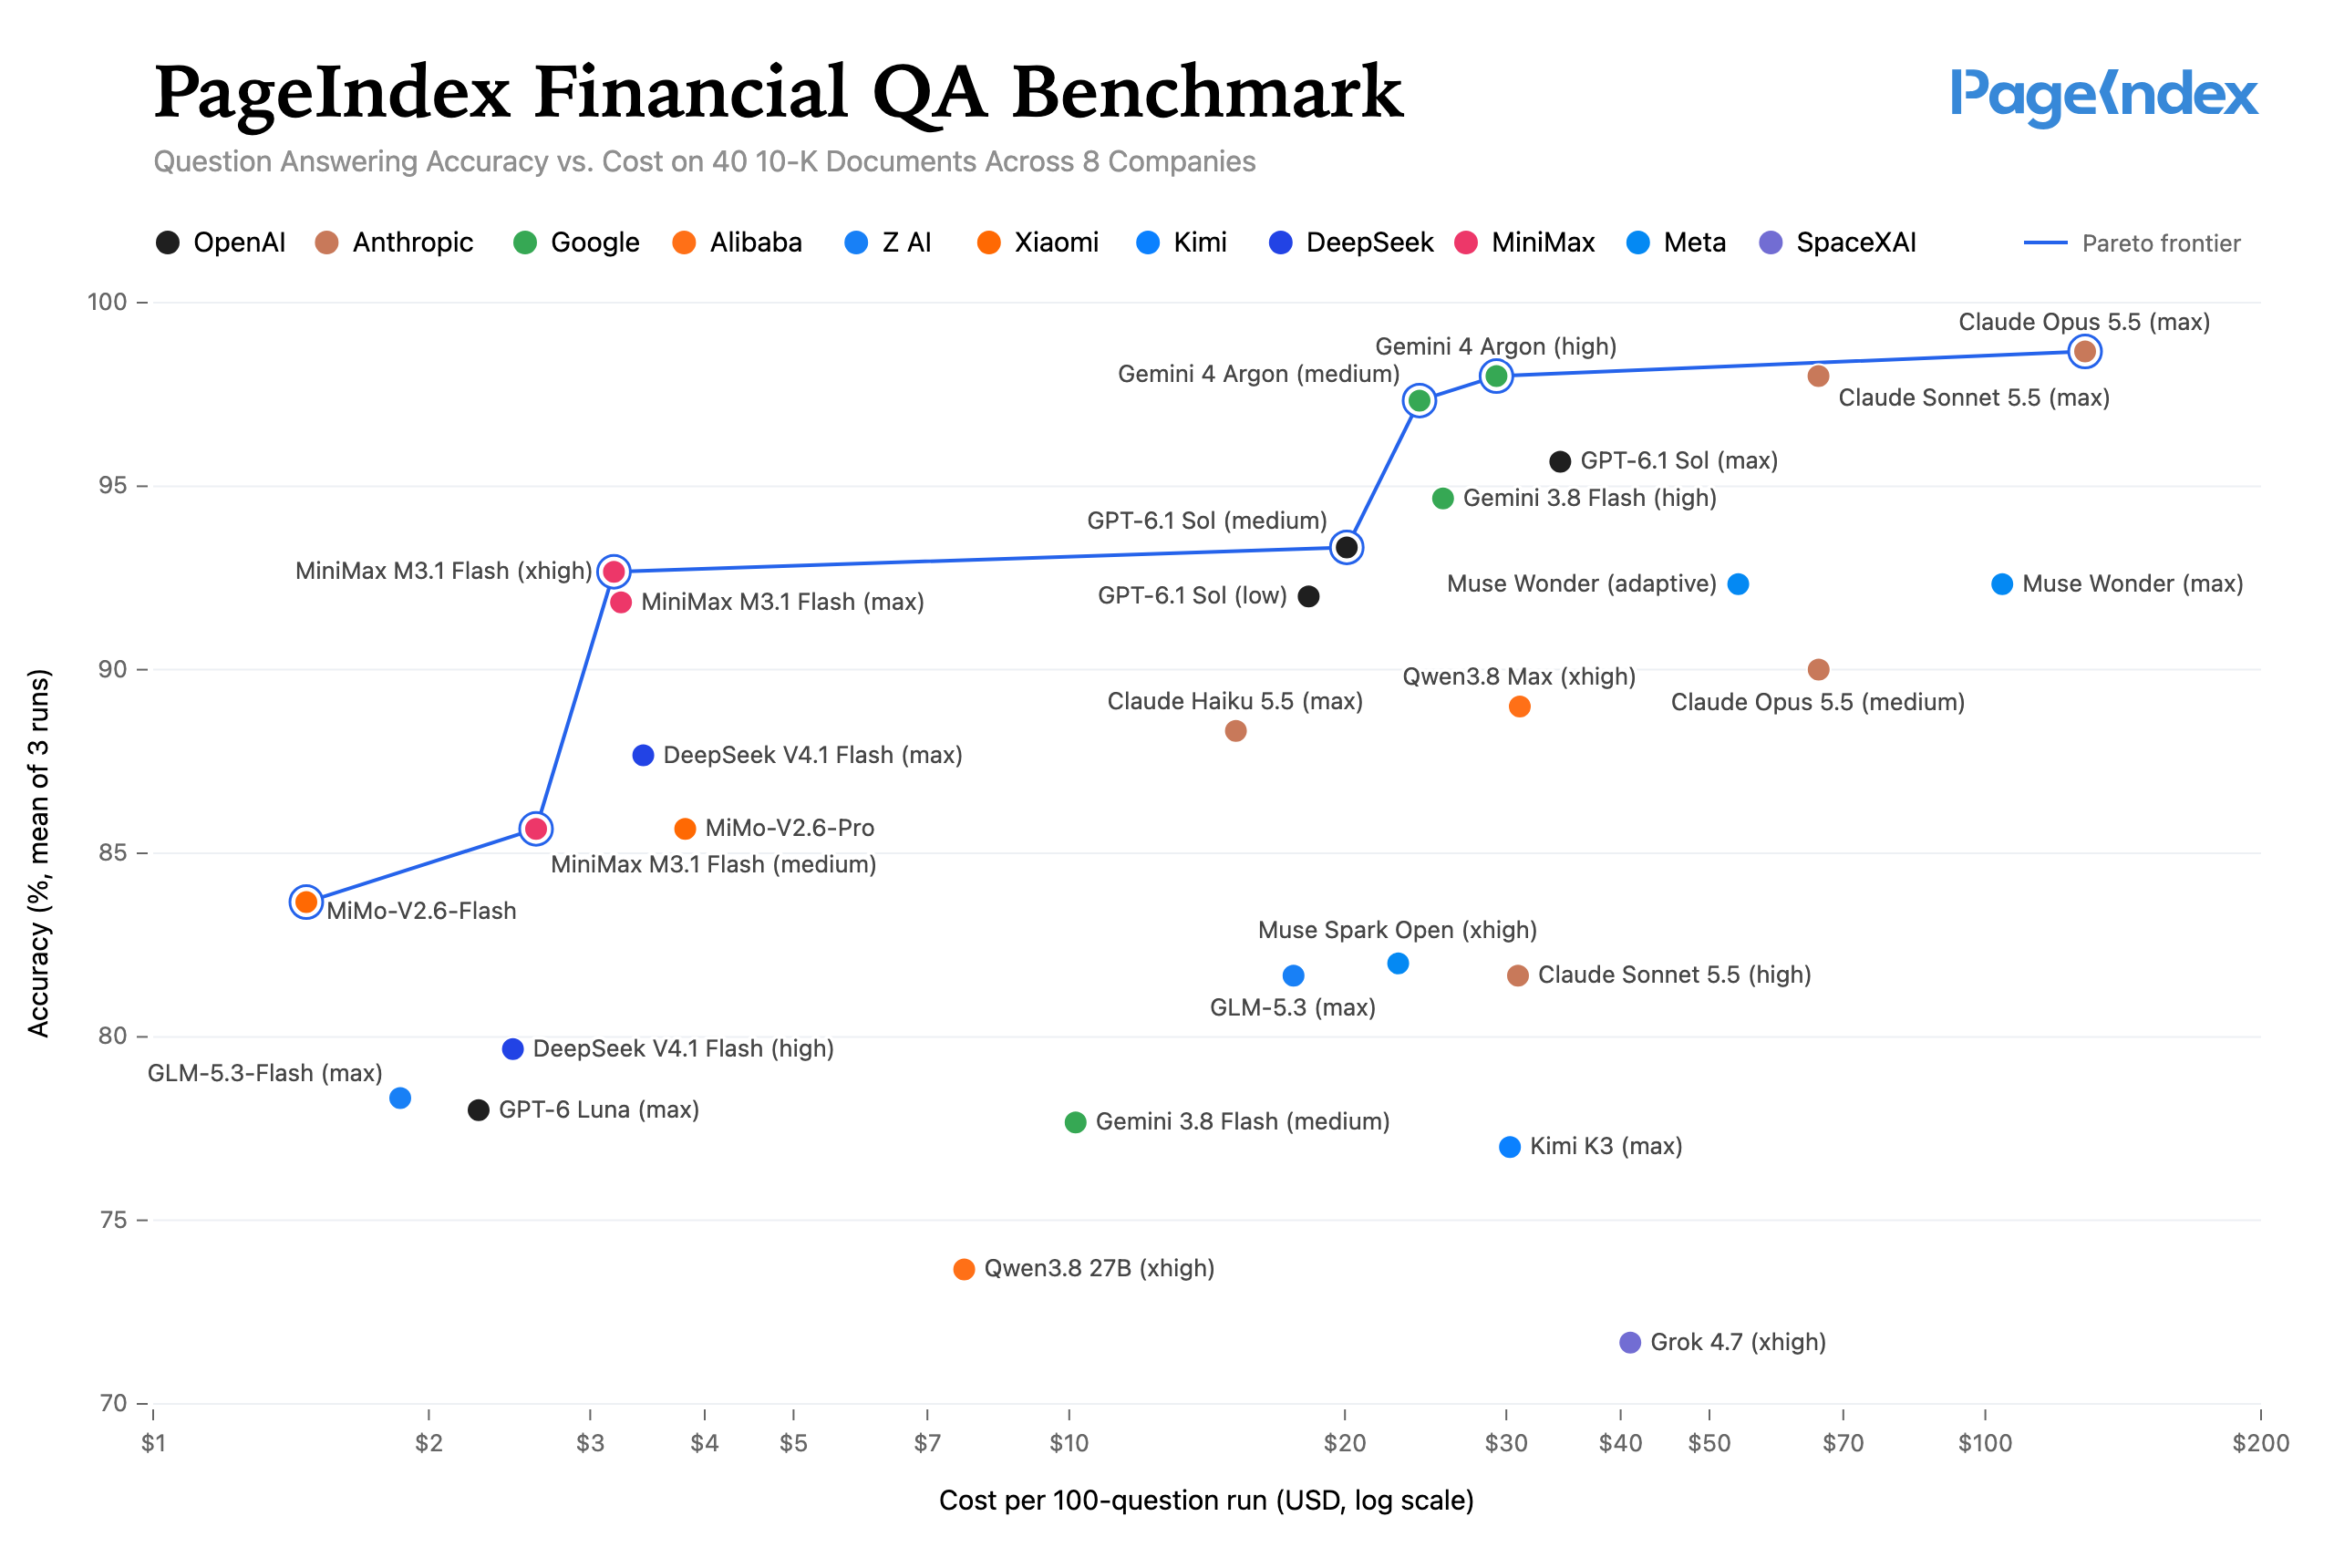
[**PageIndex Financial QA Benchmark**](https://github.com/VectifyAI/pageindex-benchmarks/tree/main/financial-qa) compares the accuracy and query cost of 34 configurations of 19 LLMs answering 100 questions over 40 Form 10-K filings from 8 companies, with PageIndex doing the retrieval. Cost is measured per 100-question run and excludes one-time indexing.
Full results, data, and reproduction instructions are in the [benchmark repo](https://github.com/VectifyAI/pageindex-benchmarks/tree/main/financial-qa).
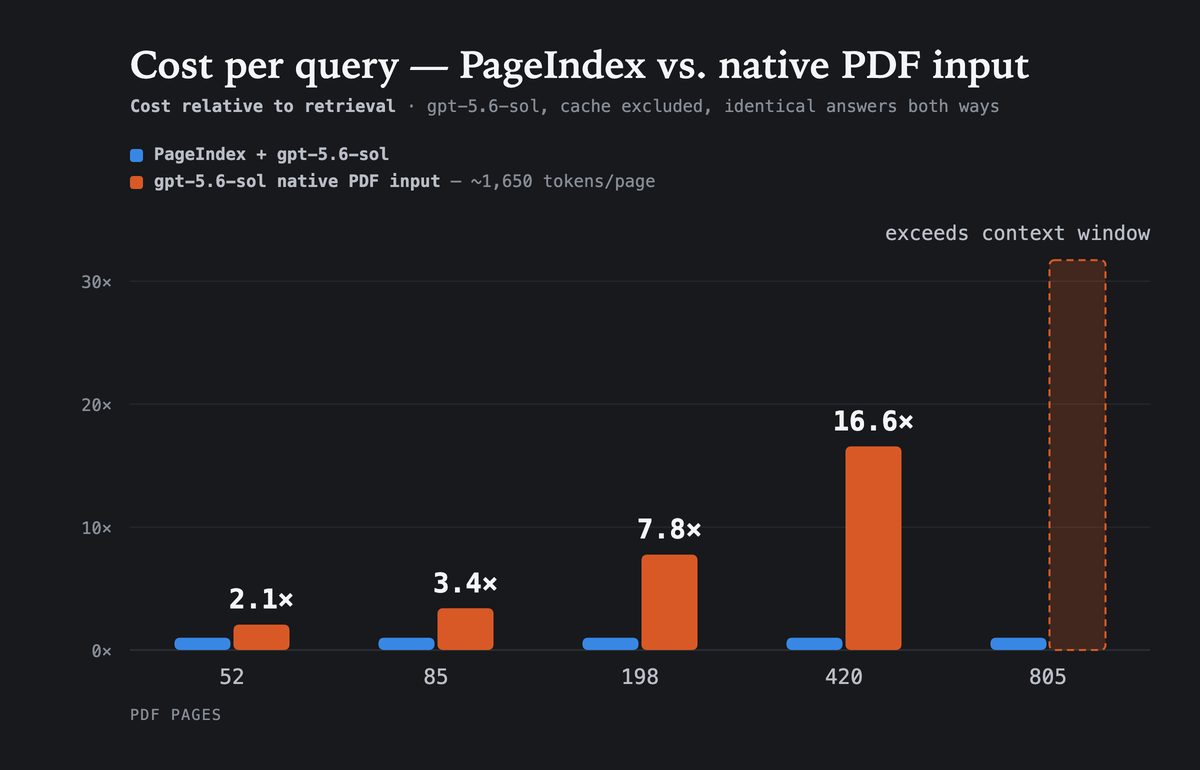
### Cost per query vs. native PDF input
The alternative to retrieval is handing the model the whole PDF on every question. That cost grows with the document; PageIndex's does not, because it reads only the nodes its reasoning reaches. On documents where both routes return the same answer, native PDF input costs **2.1Γ more at 52 pages and 16.6Γ more at 420** (`gpt-5.6-sol`, prompt caching excluded) β and at 805 pages the document no longer fits in the context window at all.
### Leading accuracy on FinanceBench
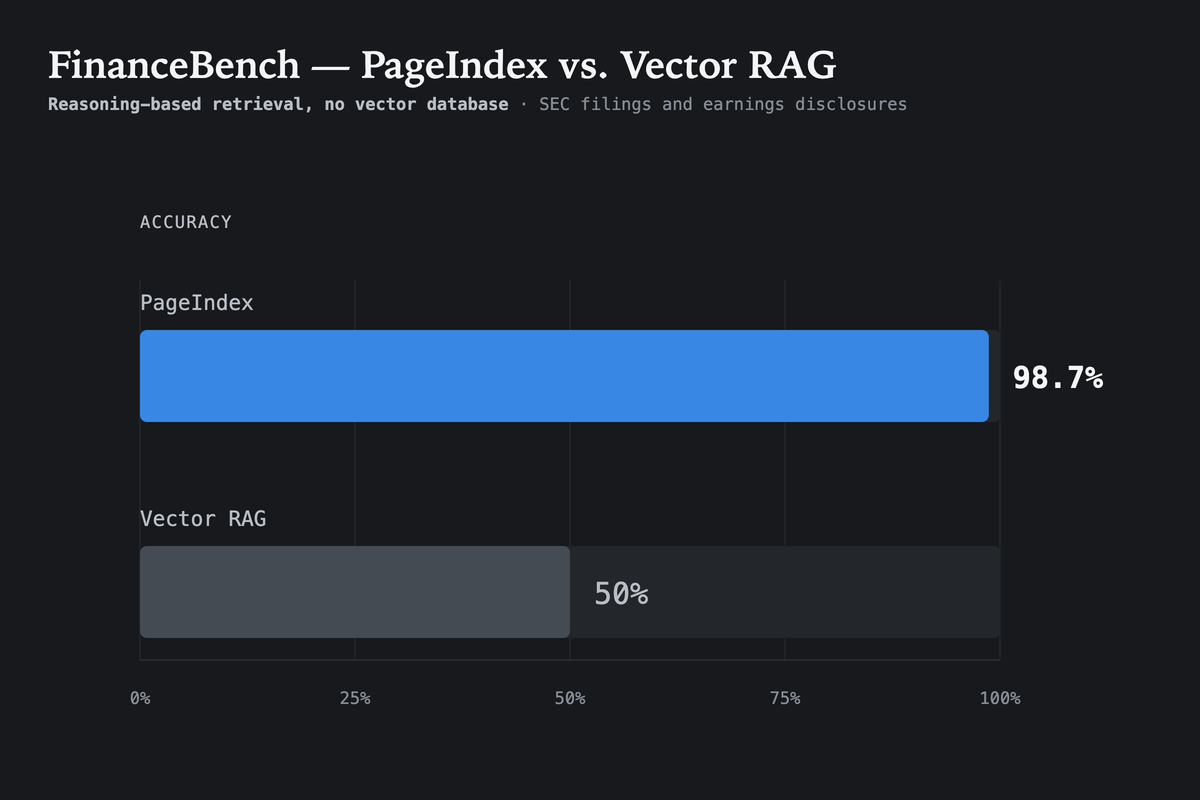
PageIndex reached a state-of-the-art [**98.7% accuracy**](https://vectify.ai/blog/Mafin2.5) on [FinanceBench](https://arxiv.org/abs/2311.11944) (financial document QA benchmark), vastly outperforming vector-based RAG.
Explore the full FinanceBench [evaluation results](https://github.com/VectifyAI/Mafin2.5-FinanceBench) and the [blog post](https://vectify.ai/blog/Mafin2.5).
# PageIndex Cloud
The open-source version is ideal for text-heavy PDFs and local workflows. With **PageIndex Cloud, document indexing and storage run in the cloud**: PageIndex handles parsing, OCR, image understanding, tree-index construction, and managed storage for you. The chat and retrieval layer remains **compatible with your model**, so you can search the cloud-hosted index using the model provider your application already uses.
Moving indexing and storage from Local to Cloud only requires a [PageIndex API key](https://developer.pageindex.ai/):
```python
import os
from pageindex import PageIndexClient
os.environ["PAGEINDEX_API_KEY"] = "your-pageindex-key"
os.environ["OPENAI_API_KEY"] = "your-openai-key"
client = PageIndexClient(
index="cloud", # build and store the index in PageIndex Cloud
chat="gpt-6-sol", # use your preferred compatible model for chat
)
doc_id = client.submit_document("report.pdf", wait=True)["doc_id"]
print(client.chat("What was the 2023 operating margin?", doc_id=doc_id))
```
| | **Local** | **Cloud** |
|---|---|---|
| Handles | Text-based PDFs | Text-based, scanned, and image-rich documents |
| Indexing | On your machine | Managed by PageIndex |
| Storage | Local directory | Cloud storage |
| Citations | Page-level | Block-level |
| OCR & image understanding | β | β |
| [Metadata](https://docs.pageindex.ai/sdk/documents#metadata) | β | β |
| [Folders](https://docs.pageindex.ai/sdk/documents#folders-cloud) | β | β |
| [MCP server](https://docs.pageindex.ai/mcp) | β | β |
### More About PageIndex Cloud
- [Scale PageIndex to Millions of Documents](https://pageindex.ai/blog/pageindex-filesystem): **PageIndex File System** is a Cloud-only, file-level tree indexing layer that lets PageIndex reason over an entire corpus, not just a single document.
### Ready to Try It?
- Get a [PageIndex API key](https://developer.pageindex.ai/)
- Read the [PageIndex Cloud documentation](https://docs.pageindex.ai/)
For dedicated deployment (VPC or on-premises), [contact us](https://pageindex.ai/contact) or [book a demo](https://calendly.com/pageindex/meet).
---
# β Support Us
Leave us a star π if you like our project. Thank you!
Please cite this work as:
```
Mingtian Zhang, Yu Tang and PageIndex Team,
"PageIndex: Next-Generation Vectorless, Reasoning-based RAG",
PageIndex Blog, Sep 2025.
```
Or use the BibTeX citation.
```bibtex
@article{zhang2025pageindex,
author = {Mingtian Zhang and Yu Tang and PageIndex Team},
title = {PageIndex: Next-Generation Vectorless, Reasoning-based RAG},
journal = {PageIndex Blog},
year = {2025},
month = {September},
note = {https://pageindex.ai/blog/pageindex-intro},
}
```
---
Β© 2026 [PageIndex AI](https://pageindex.ai)