# hotclip
**Repository Path**: xiaohaohu/hotclip
## Basic Information
- **Project Name**: hotclip
- **Description**: No description available
- **Primary Language**: Unknown
- **License**: AGPL-3.0
- **Default Branch**: main
- **Homepage**: None
- **GVP Project**: No
## Statistics
- **Stars**: 0
- **Forks**: 0
- **Created**: 2026-09-24
- **Last Updated**: 2026-09-24
## Categories & Tags
**Categories**: Uncategorized
**Tags**: None
## README
Local transcription now checkpoints completed windows and resumes after interruption. Transcript editing adds cross-sentence search, virtualized long lists, and timing calibration with listen/apply/undo. After a full visual scan, the same search also finds confirmed scene descriptions and on-screen text, with one-click seeking to each timestamp. Exports improve language-aware caption readability. See the [speech and long-transcript guide](docs/local-speech.md) for optional local Qwen3-ASR setup and reproducible model evaluation.
When exact search finds nothing, the transcript workspace can opt into **Similar speech** to find recognition results that differ by one character. Results are labeled approximate and can be listened to before selecting a clip.
**Search to clip**: browse speech and visual matches in time order, filter by source, seek matched words, play context, then review preselected full sentences in the picker. Estimated timing stays labeled; long transcript picking is virtualized, and added candidates support undo/redo.
When speaker detection is enabled for a conversation, the transcript workspace can filter by S1 / S2 and keep search, similar-speech matches and clip preview within that speaker.
## Export progress and cancellation
Exports identify preparation, translation, publish copy, variants, encoding and finalization. Cancel during preparation, wait for cleanup, then retry without losing the candidate selection. A second desktop export cannot replace an active job. Progress stays below 100% until delivery completes. SRT-only export retains word timings even when burned captions are off.
Cuts, jump cuts, audiograms, compilations and web-caption renders write into a private folder beside the destination, then replace it only after successful encoding. Failed or cancelled encoding preserves the previous target; previously completed clips stay available. Normal cancellation cleans staging files. A forced process exit can leave hidden `.hotclip-write-*` folders; remove them only after confirming no export is active. Protection applies to each encoding operation, not an all-or-nothing batch rollback.
## Why HotClip
- **Actually free, not a trial**: AGPL-3.0 open source — no watermark, no credits, no length caps, no account. There is no crippled free tier, and no quota that expires at month's end
- **Your footage never leaves your machine**: transcription, captions, cutting and export all run locally — unreleased footage and client material stay yours
- **Every cut comes with receipts**: virality score + opening hook + reasoning + four-dimension review, plus visible caption-timing provenance and review ranges — the AI never guesses timestamps or fabricates confidence
- **Automatic cuts listen for speech first**: a sub-1MB local detector independently checks the word timeline; word gaps that still contain speech stay intact, edge movement is strictly capped, and uncertain evidence preserves the original cut exactly
- **Denoise only when needed, at the tier you choose**: Basic keeps the conservative fixed filter; Smart downloads an optional ~10MB 48kHz local dialogue model, processes the fully assembled edit before SFX/BGM, and truthfully falls back to Basic when unavailable
- **Live chat feeds highlight detection**: the chat log next to your recording is auto-discovered (BililiveRecorder .xml and Douyin-recorder .jsonl both work), gifts and superchats weighted, spam-proof — the audience voting second by second, evidence most tools never even look at
- **Ready to post, not just cut**: vertical clips + dynamic captions + covers + post copy + per-platform publish packs, all in one run
- **Interrupted work picks up safely**: source, transcript, candidates, selections and hand-tuned cuts recover after restart; folder watch and webhooks share a durable queue with retry and cancel
- **Real projects, not disposable tasks**: a project workspace manages multiple edits with offline/changed-source relinking; selections, copy, boundaries and transcript fixes all undo/redo, even after reopening
- **Analysis and render always see the same picture**: motion/shots, timeline thumbnails, facial emotion and optional vision review all bind the globally selected video stream; executable PQ/HLG paths get a safe SDR analysis preview, and evidence caches isolate picture plus colour decision
- **Long videos get faster on repeat**: identical base renders come straight from a bounded local cache; H.264 video is stream-copied only for keyframe-aligned, pixel-unchanged single cuts, while audio processing remains intact and every uncertain case falls back to accurate encoding
- **Picture correction only when evidence calls for it**: on non-HDR-detected sources, optional adaptive finishing measures retained frames and makes a restrained correction only for clearly dark, flat or oversaturated footage; any detected PQ/HLG bypasses this SDR-domain pass, while healthy sources stay untouched and monochrome is never force-coloured
- **HDR in, predictable SDR out**: automatic conversion requires an explicit PQ/HLG transfer plus complete, supported primaries, colour matrix and range; qualifying sources are tone-mapped in linear light to tagged SDR BT.709, while SDR and unknown transfers stay on the existing path
- **Publishing teaches the next cut**: every export gets a stable content ID; multi-version exports form local A/B groups and only receive a direction when platform, publish window and sample evidence are comparable
- **Clips while you sleep**: a 24/7 watch folder turns finished recordings into clips; one-click health diagnostics catch missing tools/models first, while CLI / MCP make it a one-sentence agent deliverable
## How to turn a long video into shorts — in three steps
1. **Import**: drop in a podcast, livestream replay, lecture or vlog (MP4 / MKV / MOV / FLV / TS, audio-only too), or paste a public Bilibili / YouTube-style video URL. The official resolver is downloaded and verified on first use; the source lands locally and enters the same on-device workflow
2. **Pick highlights**: local word-level transcription → the AI reads the whole transcript and nominates quotables, conflicts and peak moments — each with a **virality score, an opening hook and its reasoning**, cut points accurate to the word; untick anything you don't like
3. **Export**: one click produces vertical 9:16 clips — comfort-first reframe, dynamic word-synced captions, title cards and -14 LUFS loudness. PQ/HLG becomes tagged SDR BT.709 only when its primaries, colour matrix and range are complete and supported; otherwise the video stays unconverted and the result says so — plus a cover image and post copy, ready for **TikTok / Reels / Shorts / Douyin / Bilibili**
## Screenshots

A real workbench — preview, timeline, candidate table and inspector on one screen: live-chat and loudness heat curves are drawn right on the timeline, and candidate segments sit on the peaks, so "why this segment" is visible at a glance. Every candidate ships a virality score, four-dimension breakdown and word-accurate cut points; weak picks are auto-flagged, and you make the final call.

① Import a podcast / livestream replay / lecture — everything is processed locally, nothing is uploaded |

② Pick an ASR engine — the source stays docked in the workbench; three local tiers (SenseVoice / Paraformer / FireRedASR2) plus an optional cloud tier |

③ Transcript tab — timestamped, click-to-fix, click a timecode to seek the preview; the foundation for highlights and captions |

④ One-click export — reusable export schemes, vertical clips ready to post, with cover images and clips.json metadata |
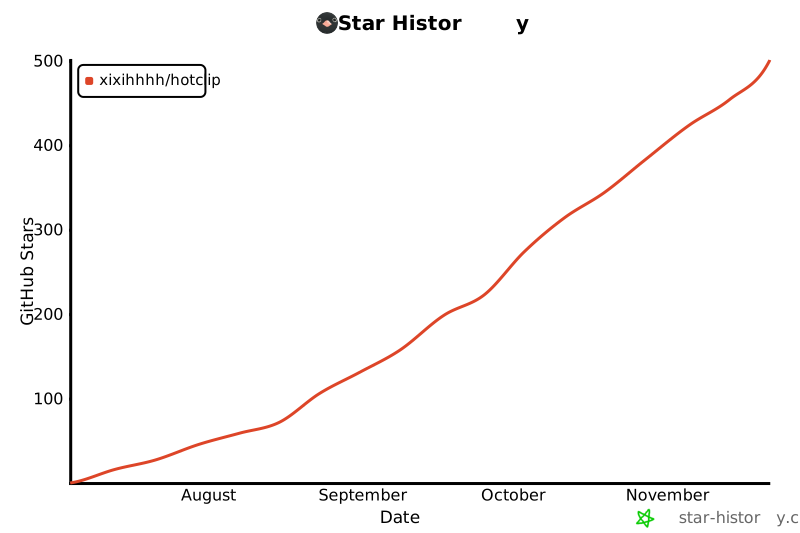
> Real UI, driven with a sample livestream-selling replay. **If the cuts look right to you, a ⭐ helps more creators escape credit-metered clipping tools — and Star + Watch gets you release notifications.**
## ⬇️ Download
**[Get the latest release »](https://github.com/xixihhhh/hotclip/releases/latest)**
| Platform | File | Notes |
|---|---|---|
| Windows installer | `HotClip-x.y.z-win-x64.exe` | Double-click to install |
| Windows portable | `HotClip-x.y.z-win-x64.zip` | Unzip & run |
| macOS (Apple Silicon) | `HotClip-x.y.z-mac-arm64.dmg` | Drag into Applications |
| Linux (experimental) | `HotClip-x.y.z-linux-x64.AppImage` | `chmod +x` then run; add `--no-sandbox` if it fails to launch with a sandbox error |
> ⚠️ Builds are currently unsigned: on Windows SmartScreen choose "More info → Run anyway"; on macOS right-click → Open on first launch (or allow it under System Settings → Privacy & Security). Code signing is on the roadmap.
>
> No Python, no Docker, no command line, no account — a real desktop app you double-click.
## Who it's for
- **Streamers & clippers**: clip your own VODs into highlight shorts right after the stream; the 24/7 **watch folder** turns finished recordings into clips while you sleep; live-chat density feeds straight into highlight detection (both Bilibili danmaku .xml and Douyin recorder .jsonl chat logs work)
- **Podcasters**: audio-only episodes still become video — an **audiogram waveform** plus quote captions turns your podcast into vertical clips
- **Educators & marketers**: lectures, webinars and demos become snackable clips with covers, titles and metadata — with a banned-words lint before publish
- **Talking-head creators**: silences, ums and stutters removed automatically; click-to-fix transcripts and a custom-vocabulary glossary keep names right, episode after episode
## How it compares (free Opus Clip alternative)
Commercial clippers meter **credits per source minute** (a 2-hour podcast burns a month's quota; credits expire monthly), require **cloud uploads**, ship **black-box scoring**, or paywall captions. Open-source alternatives are CLI/Docker tools most creators can't install. HotClip fixes both sides:
| | HotClip | OpusClip / Klap / Vizard (SaaS) | CapCut smart clipping | FunClip / autoclip (open source) |
|---|---|---|---|---|
| Price | **Free & open source** | $15–29+/mo, credits per source minute, expire monthly | Core features paywalled | Free |
| Your footage | **Stays on your machine** | Mandatory cloud upload | Mostly cloud | Local |
| Watermark / caps | **None** | Free tier: watermark, caps, projects expire in 3 days | Some restricted | None |
| Account | **No sign-up** | Account required, projects deleted on unsubscribe | Login required | None |
| Beginner-friendly | **Double-click installer** | Web app, easy | Easy | CLI / Docker / self-hosted |
| Cut quality | **Word-aligned, reasoning attached, veto anything** | Black-box scoring | Black box | Sentence-level, unranked |
| Vertical captions | **9:16 reframe + dynamic captions built in** | Yes (paid tiers) | Auto-captions paywalled | Mostly no vertical reframe |
Competitor info verified 2026-07. Deep dive: [HotClip vs OpusClip](https://xixihhhh.github.io/hotclip/alternatives/opus-clip.html)
## Features
> The full pipeline — import → AI highlights → vertical clips with captions — ships today. Expand each group for details; the details are all real features, not adjectives.
### 🎙️ Local transcription: three engines, word-level timestamps
Already have a transcript? Choose **Import subtitles** on the transcription screen and select a UTF-8 SRT / WebVTT aligned to the current source. Review, correct and pick sentences immediately; start AI detection when needed. Import runs without ASR and leaves the transcription cache intact. Original cue boundaries are preserved; within-cue word timing is marked as estimated and appears in the timing-review filter. Manual splices strictly respect your selected boundaries.
CLI `transcribe`, `highlights` and `clip` accept `--subtitles "/path/original.srt"`; all three MCP tools accept `subtitlePath`. For structured output with timing provenance, run `pnpm cli transcribe "/path/video.mp4" --subtitles "/path/original.vtt" --json`. Use one original-language transcript track, up to 5 MB, 20,000 cues and 100,000 words. Overlapping, unordered, out-of-range or streaming-clock-mapped subtitles produce an actionable error instead of silently dropping dialogue.
Fast SenseVoice (5 languages, 170MB) / balanced Paraformer / most-accurate FireRedASR2 (Mandarin, dialects, code-switching) — all local, CPU-friendly, auto-downloaded with resume support; optional cloud tier (ElevenLabs, your key, audio track only).
Details: transcript cache · click-to-fix transcripts · hotword glossary · speaker diarization
- **Local transcript cache**: reopen the same file and jump straight to highlight picking; invalidated when the file or engine changes
- **Inline transcript correction**: hover any sentence and fix it in place; captions, translation and post copy all use the corrected text, while rebuilt timing is explicitly marked and filterable for review
- **Hotword glossary**: fix a name once, apply to every matching sentence, and every future transcript auto-corrects (whole-word matching, longest wrong term wins); glossary updates replay from cache — no re-recognition
- **Speaker diarization**: one toggle (local pyannote + 3D-Speaker, zero upload) labels who's speaking; the AI picks segments per speaker and never stitches two people out of context; bubble captions can color per speaker
### 🔥 AI highlights: nine evidence channels, every cut with receipts
The LLM only picks *which part* and must quote the transcript; timestamps come from **reverse-aligning the word-level transcript** — the AI never guesses times. Every candidate ships with a virality score, hook, reasoning and four-dimension review; weak picks are flagged "not recommended".
Details: review gate · chat/emotion/vision signals · reference clips · cost funnel · product mode
- **AI review quality gate**: a strict second-pass blind reviewer scores hook / structure / value / trend with one-line rationales, plus a printable teaser line
- **Virality score = ranking, not astrology**: dimension-weighted totals normalized by relative rank within the batch (76–99), immune to LLM scoring drift — honestly labeled a ranker, not a view-count oracle
- **Audio-visual evidence**: loudness peaks, shot-change density and lightweight motion peaks are collected locally and injected into judgment; the workbench renders motion as a visible timeline curve
- **Live-chat density signal (Bilibili & Douyin)**: auto-discovers the chat file next to a recording — BililiveRecorder .xml and Douyin-recorder .jsonl both work; sliding-window density with hype-word weighting, plus interaction events (superchats, memberships, gifts, follows, like bursts) weighted on their own tier — money and action votes beat plain messages. Per-sender caps stop one spammer from faking a hot moment, and sudden surges score extra — the audience voting second by second, the strongest evidence there is
- **Signal resonance & focused compute**: a moment is trusted when multiple signals fire together — loudness alone might be BGM, chat alone might be spam; loudness + chat + laughter lighting up at once is the real thing. Motion peaks guide frame sampling while an explicit uniform reserve still covers the whole source, so early spectacle cannot hide a later quiet-but-important scene
- **Reusable local multimodal evidence**: Tier-0 signals, TransNetV2 boundaries and optional vision-scan outcomes are atomically indexed by source fingerprint, capability version and model. Desktop, CLI, MCP, folder watch and webhooks reuse the same results; the 64MB LRU index rebuilds corrupt/stale entries automatically and never persists a vision API key
- **Facial-emotion peaks (zero-config)**: YuNet + FER+ (MIT-licensed, a few MB) find laughter/surprise/excitement peaks — visual evidence without installing anything
- **Visual peak signal (optional)**: fresh installs prefill local Ollama `qwen3.5:4b`, using one multimodal model for text plus nine-frame contact sheets to find visual moments the transcript cannot see; an unavailable endpoint is skipped without blocking transcript-only detection
- **AI visual review (optional)**: after detection, top candidates get a contact-sheet look-over by a vision model — striking visuals boost the score, lifeless visuals demote signal-driven candidates, title/visual mismatches get flagged, and the scene note lands in the reasoning; free with local Ollama, or drop an API key into vision settings for a cloud model
- **Reference-clip driven detection**: hand in a viral clip to model after — its pacing is measured locally and steers selection (CLI `--reference`)
- **Review feedback loop**: kept/rejected candidates land in a local preference file steering the next run — it learns your taste, and the data never leaves your machine
- **Real-performance feedback loop**: import platform-exported CSV/JSON metrics with `pnpm cli feedback`; HotClip locally learns the topic, hook, and duration patterns behind high/low performers. Desktop, CLI, MCP, and watch-folder detection all use the audience evidence without copying old titles or uploading account data
- **On-device two-stage funnel**: a small local model shortlists first, then the cloud model reads the shortlist. Long transcripts use at most two concurrent screening requests; failed or unprocessed chunks remain intact when the screening deadline is reached
- **Bounded model requests**: text analysis, visual review and model-list loading stop waiting when their deadlines expire. Text and vision calls retry a transient rate limit or busy response at most once, cancellation interrupts the wait, and error messages redact echoed API keys
- **Shot-snapped cut points**: TransNetV2 (31MB ONNX, local) finds real shot changes; boundaries snap with a word-boundary guard that never clips speech
- **Product mode (live-selling)**: type product words and selection follows conversion logic (demos > pitches > price mechanics); stalling-for-engagement segments excluded
- **Clip length presets**: short 10-30s / standard 8-40s / long 40-90s — the target length is a hard constraint in the selection prompt
### 📝 Captions & copy: auto captions and post copy, one toggle each
Dynamic captions in multiple styles — keyword highlight, word pop, bubble, minimal — burned in automatically, word-timestamp driven with semantic line breaks (never chopped mid-phrase); **SRT export** and bilingual captions included; AI titles burned as top cards; post copy generated per clip.
Details: bubble captions · opening hook · bilingual · Hormozi style · banned-words lint · AIGC labeling
- **Semantic line breaking (no API key)**: lines wrap at real clause boundaries from ASR punctuation — the commercial LLM-`[br]` result from local signals, zero extra calls
- **Bubble caption engine**: built-in Chromium renders CSS captions offscreen frame-by-frame — rounded bubbles, gradient keywords, springy entrances; deterministic, same input → same output
- **Opening hook (first 3 golden seconds)**: the AI's teaser line burned large into the first ~2 seconds, avoiding the subject and title card; skipped when there's no good teaser
- **Cold open (payoff first)**: the hottest hook line spliced to the very front, then the full clip — the standard retention trick, paywalled elsewhere; skipped when the hook can't be located (never done wrong rather than done badly)
- **Flash-forward cold open**: flash the clip's most explosive 0.3-1s before the story starts, then cut back — only 0.04% of clips ship any visual hook; auto-coordinates with the climax-first cold open (one or the other), skipped when no safe peak exists
- **Hormozi-style impact captions**: big bold chunks, hard shadows, word-by-word lighting
- **Speaker-tag captions**: in multi-speaker footage, each speaker change opens with a colored "A:" / "B:" prefix (same per-speaker palette as bubble captions) so viewers never lose track of who's talking
- **Bilingual captions**: full-sentence translation burned as a second track, remapped through jump-cut compression; competitors sell this as a paid tier
- **SRT export**: timestamps already reflect the jump-cut/filler-removed output; line breaks match the burned captions exactly
- **Post copy generation**: hooky title + 3-6 niche hashtags + description per clip (8 hook angles × 5 CTA types), saved as `.post.txt` and into clips.json
- **Platform banned-words lint**: 120+ local rules over titles/copy/captions — absolute claims, medical claims, off-platform funneling flagged before publish
- **AIGC labeling (compliance built-in)**: one toggle adds the explicit on-frame badge plus implicit container metadata per China's AIGC labeling measures
### 🎬 Finishing: edits that feel hand-made
Comfort-first 9:16 reframing, silence jump cuts, filler-word removal, -14 LUFS loudness, frame-accurate cutting — with render QA and self-repair after every export.
Details: reframe · silence cuts · denoise · SFX · BGM · QA & self-repair · smart covers
- **Comfort-first smart reframing**: each shot considers every visible face; if a single moving subject or a group fits safely, the virtual camera stays locked. It follows only when the subject truly exceeds the crop, holds through brief detector flicker, returns to centre after sustained loss, and falls back safely when detections are sparse
- **Composition receipt**: `clips.json` records total, locked, group-locked, tracked, recovery and centered-fallback shots; locked framing now holds until the next shot, and jump cuts never pan through discarded source time
- **Adaptive picture finish (optional, off by default)**: reuses local Tier-0 evidence to measure luma, contrast and saturation only across each clip's final retained ranges; hard-capped correction applies only with enough evidence and a clear dark/flat/overexposed/oversaturated signal. Healthy footage stays unchanged and monochrome is never force-coloured, while jump cuts, stitched pieces and cold opens use their real retained windows and log exact measurements/adjustments in `clips.json`
- **HDR-safe colour pipeline**: automatic conversion requires PQ (SMPTE ST 2084) or HLG plus complete, FFmpeg-supported input primaries, colour matrix and range. MaxCLL or mastering-display peak metadata constrains highlights when available; otherwise FFmpeg keeps its safe automatic estimate. Qualifying sources are converted in linear light with a restrained Mobius tone map and tagged SDR BT.709 before crop, reframe, zoom or subtitles. If an HDR transfer is present but the remaining tags are incomplete or unsupported, HotClip keeps the existing render path, skips SDR-domain adaptive picture finishing and marks the result as unconverted. If colour inspection itself fails, finishing also stays off and the result says inspection failed; SDR and unknown transfers stay on their existing path. Jump cuts, stitched pieces, caption overlays, cold opens and safe QA repairs preserve the decision — with no model, download or upload
- **Screen-recording UI removal**: status bars and letterboxing detected via temporal variance and cropped out
- **Speech-aware silence jump cuts**: pauses are removed only when the span has *no words, low acoustic peaks and no locally detected speech*; missed quiet words, phoneme tails, laughter and applause survive. Optional 0.25s breathing room keeps pacing tight without suffocation; manual/stitched outer bounds stay fixed and questionable evidence falls back exactly
- **Filler-word removal**: um/uh-class fillers and stutters cut (deliberately conservative), itemized in clips.json
- **Loudness normalization**: -14 LUFS (EBU R128) per clip, measured on the spliced audio after jump cuts
- **Two explicit dialogue-cleanup tiers**: Basic retains the double-highpass + conservative spectral subtraction chain. Smart 48k downloads a SHA-256-verified ~10MB DPDFNet2 model on demand, enhances mono/stereo channels in bounded chunks for clips up to 180 seconds and stream-copies video. Model, download, decode or inference failure falls back to Basic; the completion view and `clips.json` distinguish learned / fallback / skipped without changing captions or transcript text
- **SFX cues**: a whoosh on stitch/cold-open hard cuts, a ding on the clip's emotional peak, a soft pop as the opening hook lands — rule-based placement, at most 3 per clip; effects are synthesized locally (zero assets, zero licensing), drop in your own same-named wav files to replace them
- **Background music (with ducking)**: pick any local audio file — it loops to fit the clip, sits well under the voice, ducks automatically while speech plays and fades out at the end; mixed in a separate pass with the video stream copied untouched
- **Render QA + self-repair**: black frames, long silences, frozen video, subject crop coverage, loudness, duration and mid-word cuts land in `clips.json`; semantic framing warnings ask for review, while only safe fixable faults are repaired and retained after a better re-check
- **Quality-ranked smart cover**: audio peaks propose relevant moments, then the finished clip is ranked locally for sharpness, information, exposure, tonal range and transition stability; black/white or blurred transition frames are rejected, variants take the next rank, and any probe failure returns exactly to the prior audio-peak choice
- **Frame-accurate cutting**: fast seek + re-encode; hours-long FLV/TS replays go straight in
- **Hardware-accelerated export**: automatically uses VideoToolbox / NVENC / QSV when the bundled ffmpeg supports it; an unavailable device or driver transparently retries with x264, keeping reliability intact
- **Precision cut points (Paraformer second pass)**: selected clips are re-decoded before export to repair captions, jump cuts and boundaries; matched/interpolated words, coverage and uncertain spans land in the receipt, while weak or failed alignment still falls back safely
- **Caption timing quality gate**: validates the final post-splice timeline for invalid or overlapping timing, reading speed, flashes, oversize tokens and estimated ranges; every clip records a machine-readable report in `clips.json`
- **Cancellable exports + real-time progress**: ffmpeg progress streamed live; cancel kills the encoder instantly, finished clips stay
### 🧰 Review & workflow: AI rough cut, human final cut
A clip review workbench (play in-app, drag cut points word-by-word on a waveform), platform-accurate caption safe-zone masks, brand style presets, render prefs memory.
Details: project workspace · reversible editing · restart recovery · workbench · safe zones · publish packs · topic series · variants · brand templates · dual aspect · compilation · EDL · settings
- **Project workspace**: manage multiple edits without state crossing between them; switch, rename, close or delete project documents, keep offline/changed-source projects intact, and safely relink media — deleting a project never deletes the source file
- **Reversible editing + pro shortcuts**: selections, copy/boundaries, multi-piece changes, manual clips and transcript corrections all undo/redo with bounded history persisted in the project; `Space/K` play, `J/L` ±5s, `I/O` in/out and `[/]` candidate navigation yield automatically inside inputs and modals
- **Restart-safe recovery**: the current source, transcript, candidates, selections and hand-tuned boundaries are checkpointed; reopening validates the source and restores the last stable state, never a transient detecting/exporting state
- **Clip review workbench**: play candidates in-app, drag waveform handles to fine-tune word by word (snapping to word boundaries), one-click restore of AI cuts; manually tuned clips skip shot-snapping — the machine never overrides a human decision
- **Caption safe-zone preview**: overlay each platform's real UI occlusion areas — nine presets from measured data (Douyin / Kuaishou / Bilibili / WeChat Channels / RedNote / TikTok / Reels / Shorts + generic union)
- **Platform publish packs (post right after cutting)**: per-platform folders with the video hard-linked, the cover re-cropped to that platform's aspect (RedNote 3:4, Bilibili 16:10, Channels 6:7) and post copy trimmed to platform limits, plus a manifest of what was adapted — open the folder, upload platform by platform
- **Topic-series packs (optional)**: when two or more original clips share a meaningful keyword, they are grouped and numbered in source-time order with root/per-topic manifests; variants never become fake episodes, and hard links avoid duplicate disk use
- **Multi-version variants (real differentiation for multi-account posting)**: 2-3 packagings of each clip in one run — different hook-angle title cards, opening teasers, post copy, covers from different loudness peaks; built on added value, not the frame-dropping/mirroring tricks platforms now flag as reposts
- **Brand style templates**: one highlight color, caption size/position, logo watermark — named presets applied to every clip, recorded in the receipt
- **Dual aspect ratios in one click**: vertical 9:16 plus a landscape set in one run (title card dropped, captions switch layout) — competitors export one ratio per run
- **One-click compilation**: the batch spliced into a highlights reel via stream copy (milliseconds, zero quality loss) with a `.chapters.txt` chapter file
- **EDL timeline export**: `timeline.edl` (CMX3600) with every cut including jump-cut splices — import into DaVinci / Premiere and keep refining
- **Audiogram rendering**: audio-only sources auto-compose a dark canvas + animated brand-colored waveform, captions burned as usual
- **Render prefs memory + inline title editing**: toggle combos remembered across videos; titles editable in place with file names and copy following
- **Settings page**: model storage visible and movable (cross-drive moves copy → verify → then delete), three export quality tiers (Compact measured 66% smaller), default caption style and export location
- **Update notifications**: silent check on launch, a small badge when a new release exists; offline checks fail silently
### 🛡️ Publish & survive: compliance built for 2026
Cutting well is half the game — the other half is surviving distribution: pixel-level repost detection, mandatory AIGC labeling, save-rate-weighted algorithms. This group handles that half.
Details: transform score · AI covers · AI BGM · JianYing drafts · ledger & evidence · AIGC labeling · anti-fingerprint variants
- **Transform score**: everything an export actually changed (reframe, jump cuts, captions, cards, SFX…) rolls into one score, previewed live before export, yellow card under 40 — pixel-level reposting is 2026's #1 takedown cause
- **Two-tier AI covers (optional)**: big-type vertical covers generated from clip titles — volume tier ~$0.04, premium ~$0.14 per cover (reusing your Atlas key); saved alongside the frame-grab cover, use whichever
- **AI BGM (optional)**: copyright-safe instrumental generated per stream genre, auto-wired into the voice-ducking mix chain — zero licensing risk from commercial libraries
- **JianYing draft export**: each clip lands as a JianYing (CapCut CN) draft folder with every AI cut on the timeline — rough cut in HotClip, hand off to the editor for finishing without starting over
- **Publishing feedback ledger**: every export registers a stable content ID and publishing status; a prefilled metrics CSV comes back through conservative ID or unique title matching, while unmatched/ambiguous rows stay visible and measured patterns feed the next selection pass
- **Local A/B experiment center**: multi-version exports group automatically by source candidate, export batch and platform; comparisons require one platform, publish times within 72 hours, complete metrics and at least 500 views per version, and report awaiting/insufficient/inconclusive/directional states without single-variable causal claims
- **Distribution evidence pack**: each clip's source range is logged to CSV, optionally with a ±3-minute source archive — when an authorized clip gets challenged as a repost, you have receipts
- **Transcript-timed audio muting (optional)**: mute a local editable list of sensitive terms while preserving the original transcript and captions; timing remains accurate across silence cuts and multi-piece clips
- **AIGC labeling helper**: per-platform label copy and entry-point pointers, one click to copy; a soft cap hint over 5 clips per stream (2026 algorithms reward quality over volume)
- **Anti-fingerprint variants**: the last of your multi-version variants swaps in a flash-forward opening plus seeded template jitter (subtle font-size/baseline/margin differences) — multi-account posting without visual-fingerprint collisions, all real differentiation rather than pixel tricks
### 🤖 Batch & ecosystem: CLI / MCP / Agent Skill
One-click hands-off mode + 24/7 watch folder + headless CLI + local MCP server — **the only local, no-upload clipping toolchain for coding agents**.
Details: durable task queue · watch folder · health diagnostics · CLI · MCP · Claude Code skill
- **Durable task center**: folder watch and webhooks share one single-concurrency queue with persisted stages, history and attempt counts; tasks can be cancelled or explicitly retried, in-flight work becomes "interrupted" after restart, and credentials are never stored in history
- **Long-video performance layer**: repeat exports with the same source, cuts and base effects restore an exact local base render; H.264 video is copied only for a continuous cut whose start is proven keyframe-aligned and whose pixels are unchanged. Audio still receives fades, denoise, loudness and sensitive-term muting, and any failure transparently falls back to accurate encoding. LRU storage is capped at 1GB and can be inspected or cleared separately
- **Recording watch folder (24/7)**: point it at your OBS/recorder output dir; recordings are transcribed, mined and exported the moment they finish writing ("two rounds of stable size" — half-written files are never cut)
- **Desktop health diagnostics**: one click checks FFmpeg/FFprobe, downloader integrity, eleven model roles, LLM connectivity/auth/routing, disk, transcript cache, render cache and the multimodal evidence index; missing core models can be prepared with cancel/resume, while the 1GB render cache and 64MB evidence index clear independently
- **Headless CLI** (same outputs as the desktop app):
```bash
pnpm cli transcribe vod.mp4 # on-device word-level ASR (cached)
pnpm cli highlights vod.mp4 --json # AI highlight candidates, review first
pnpm cli clip vod.mp4 --max-clips 10 --smart-denoise # managed export + smart 48k dialogue
pnpm cli feedback bilibili.csv # import real view/engagement outcomes
pnpm cli feedback-report # inspect learned winners/laggards
pnpm cli doctor --download # environment self-check + model pre-fetch
```
- **Local MCP server** (register in Claude Code / Claude Desktop) — three tools: `clip_video`, `detect_highlights`, `transcribe_video`:
```json
{
"mcpServers": {
"hotclip": {
"command": "npx",
"args": ["-y", "tsx", "src/mcp/server.ts"],
"cwd": "/path/to/hotclip",
"env": {
"HOTCLIP_LLM_BASE_URL": "http://localhost:11434/v1",
"HOTCLIP_LLM_MODEL": "qwen3:8b"
}
}
}
}
```
- **Official agent skill** — paste this into Claude Code / Codex and the agent installs everything itself:
> Install HotClip as my local clipping skill: `git clone https://github.com/xixihhhh/hotclip.git && cd hotclip && pnpm install`, then copy `skills/hotclip/` into my agent skills directory (`~/.claude/skills/hotclip/` for Claude Code) and configure the LLM env vars per `skills/hotclip/SKILL.md`. Verify with `pnpm cli highlights` on a test video.
- **clips.json processing receipt**: what the pipeline did to each clip (caption style, reframe mode, jump-cut ratio, speech-evidence coverage/protected gaps, alignment coverage, caption lint, cover-selection mode/score, fillers removed and source colour decision, including an unconverted-HDR flag) — fully auditable, pipeline-ready
- **Golden quality evaluation**: `pnpm quality:eval [fixture.json]` reports CER/WER, median/P95 word-boundary error and highlight recall@3/@5 locally, so model and threshold changes can be compared on the same evidence
- **Local vision-model comparison**: `HOTCLIP_VISION_MODELS=qwen3-vl:4b,qwen3.5:4b pnpm quality:eval:vision` runs the same demo clips through HotClip's exact contact sheets and structured parser, reporting success rate, latency and visual evidence. Ollama manages the models; HotClip does not bundle multi-gigabyte weights
- **Bring your own AI (or none)**: free local models by default; plug in [Atlas Cloud](https://www.atlascloud.ai), fal.ai or any OpenAI-compatible endpoint — or local Ollama for a fully offline pipeline
## What's new
**[v0.32.0](https://github.com/xixihhhh/hotclip/releases/tag/v0.32.0)**: fixes permanent black screens and failed seeking in the Windows review desk when multiple videos share a media stream; preview errors now show the actual code; fetched model lists now have an explicit clickable dropdown while manual entry remains available.
**[v0.31.0](https://github.com/xixihhhh/hotclip/releases/tag/v0.31.0)**: the transcript workspace can filter multi-speaker conversations by S1 / S2, with search, similar-speech matches and clip preview following the filter.
**[v0.30.0](https://github.com/xixihhhh/hotclip/releases/tag/v0.30.0)**: opt-in similar-speech search finds recognition results that differ by one character when exact search has no result, with an explicit approximate-match label and audition before selection.
**[v0.29.0](https://github.com/xixihhhh/hotclip/releases/tag/v0.29.0)** (2026-09-16): unified speech/visual search, word seeking, context playback and preselected clips; a virtualized long-transcript picker, bounded model requests with cancellable transient recovery, and limited local screening concurrency with failed-chunk retention. [Release notes](docs/releases/v0.29.0.md).
**[v0.28.1](https://github.com/xixihhhh/hotclip/releases/tag/v0.28.1)** (2026-09-12): fixes empty responses from Qwen3/QwQ hybrid-thinking models, lowers the Small dynamic-caption size to 0.68, and lets Windows review playback retry after a media-load failure. [Release notes](docs/releases/v0.28.1.md).
**[v0.28.0](https://github.com/xixihhhh/hotclip/releases/tag/v0.28.0)** (2026-09-05): **Subtitle import and long transcripts** (SRT / WebVTT, cross-sentence search, selective alignment preview and undo); **resumable local speech** with optional Qwen3-ASR; **language-aware caption pacing** and **safer exports** with preparation-stage cancellation, safe output replacement, direct retry and SRT-only output. [Release notes](docs/releases/v0.28.0.md).
**[v0.27.0](https://github.com/xixihhhh/hotclip/releases/tag/v0.27.0)** (2026-08-31) "Make the voice clear before adding the polish": **48kHz smart dialogue enhancement** (an explicit Smart tier downloads a SHA-256-verified ~10MB DPDFNet2 model on demand, processes channels in bounded chunks and stream-copies finished video); **correct publish-audio order** (runs after stitched/cold-open assembly but before SFX/BGM, with loudness measured after enhancement); **availability-first fallback** (model, download, decode or inference failure transparently reuses the exact Basic chain, while Off/Basic behavior stays unchanged and the completion view plus `clips.json` reports learned/fallback/skipped truthfully); **updated local multimodal preset** (fresh installs default the optional Ollama vision endpoint to `qwen3.5:4b`, sharing one model across text and contact sheets, with a reproducible VLM comparison command). Desktop, CLI and MCP share the same tier semantics; the official 48k model runtime smoke and FFmpeg integration regressions pass.
**[v0.26.0](https://github.com/xixihhhh/hotclip/releases/tag/v0.26.0)** (2026-08-31) "Tighter cuts, without gambling on a single phoneme": **local speech-activity evidence** (reuses the bundled sherpa-onnx native runtime with one SHA-256-verified 629KB model — no Python or audio upload); **safe automatic edges** (only corroborated VAD/word evidence may protect outer speech within a hard 0.6s movement cap and constrain later shot snapping; manual and stitched outer bounds never move); **three-gate jump cuts** (a span is removed only when word-free, peak-quiet and VAD-negative, retaining quiet words missed by ASR); **selected-audio parity** (speech and peak evidence explicitly map the same audio track as final render); **auditable exact fallback** (`clips.json` records coverage, edge deltas and protected gaps, while long windows, low coverage, model or decode failure preserve prior behavior). Verified with a real synthesized-speech runtime smoke and multi-track FFmpeg regression.
**[v0.25.0](https://github.com/xixihhhh/hotclip/releases/tag/v0.25.0)** (2026-08-30) "Analyze the right picture, publish the right frame": **selected-picture parity across analysis** (motion/shot/visual statistics, TransNetV2, facial-emotion frames, VLM contact sheets, candidate review, timeline filmstrips, UI-band detection and face reframing all bind the same global video stream as final render); **HDR analysis preview** (only complete executable PQ/HLG paths receive the verified SDR preview before resize or measurement; SDR and incomplete HDR retain fail-open behavior); **cache isolation** (Tier-0, shot and vision evidence identities include the selected stream and colour-plan version); **quality-ranked covers** (audio peaks plus uniform reserve propose moments, then bundled FFmpeg scores the final post-QA clip for sharpness, information, exposure, tonal range and short-neighborhood stability; unsafe frames are rejected, variants use the next rank, and failures preserve the exact old timestamp). No new model, dependency, download, upload or cloud cost; a real dual-video PQ fixture and four-scene cover golden set stay in regression.
**[v0.24.0](https://github.com/xixihhhh/hotclip/releases/tag/v0.24.0)** (2026-08-30) "HDR in, predictable colour out": **strict metadata gate** (automatic conversion requires an explicit PQ/SMPTE ST 2084 or HLG/ARIB STD-B67 transfer plus complete, supported primaries, colour matrix and range; available MaxCLL/mastering peak metadata guides the highlight bound, while SDR and unknown transfers keep their existing pixel treatment); **safe ambiguity and failure handling** (incomplete/unsupported HDR stays unconverted, while a probe failure is labelled separately; both keep SDR-domain adaptive finishing off, and desktop/CLI/MCP plus `clips.json` agree on the state); **deterministic multi-track selection** (probe, peak metadata, render and cache bind the same selected picture; single-video SDR keeps its pixel treatment and stream-copy decision); **linear-light SDR delivery** (qualifying input is converted with explicit source tags and a bounded Mobius tone map to tagged BT.709/yuv420p before crop, reframe, zoom, subtitles or watermarks); **full render-path parity without new weight** (continuous cuts, silence jump cuts, multi-piece stitches, cold opens, Chromium caption overlays and retained QA repairs keep the same decision, with no new model, asset download, API call or footage upload).
**[v0.23.0](https://github.com/xixihhhh/hotclip/releases/tag/v0.23.0)** (2026-08-30) "What the picture says should count as evidence": **on-screen text evidence** (reuses the already-enabled full-stream scan and candidate review — no OCR install and no extra model call; keeps only text that can be transcribed confidently, such as product names, prices, scores, headings and slide facts, leaving uncertainty blank); **static content is no longer invisible** (low-energy price cards and slides with clear text receive reserved evidence slots, improving product, course and review clips); **structured visual review** (observed scene, visual score, title match and visible text flow through candidates, CLI/MCP output and `clips.json`, with a bilingual workbench receipt); **better-grounded covers** (AI covers prefer the scene actually observed by candidate review over a transcript-only guess). The existing optional vision switch remains the boundary: zero added cost when off and fail-open when unavailable.
**[v0.22.0](https://github.com/xixihhhh/hotclip/releases/tag/v0.22.0)** (2026-08-30) "Fix the picture only when the evidence says so": **adaptive picture finish** (one explicit, default-off option shared by desktop schemes, CLI `--auto-enhance` and MCP); **clip-local measurement** (the existing 4fps Tier-0 decode now retains luma low/mean/high and saturation, then evaluates only final kept ranges after jump cuts or stitching — no new model or full decode); **restrained hard caps** (subtle brightness, contrast, saturation and gamma changes only for sufficiently sampled footage that is clearly dark, flat, overexposed or oversaturated; healthy footage emits no filter and monochrome is never force-coloured); **render-path parity** (continuous cuts, jump cuts and cold-open windows receive the corresponding plan after crop/scale and before captions/watermarks); **auditable and cache-safe** (`clips.json` records measurements, reasons and exact adjustments, render-cache identity includes the derived plan, and extreme recordings retain evenly bounded source coverage)
**[v0.21.0](https://github.com/xixihhhh/hotclip/releases/tag/v0.21.0)** (2026-08-30) "Don't just export — prove the picture survived": **frozen-frame QA** (the existing FFmpeg pass flags near-static spans lasting 3+ seconds, including a freeze that runs to EOF); **subject-coverage receipt** (reuses existing YuNet samples to measure partially and severely cropped faces against the final vertical trajectory, with no extra model pass); **true shot locks** (locked compositions hold until the next shot instead of drifting toward it); **jump-cut-safe camera motion** (crop trajectories switch at retained seams instead of interpolating through discarded source time). Freeze and composition findings are review-only semantic warnings, never risky automatic recuts.
**[v0.20.0](https://github.com/xixihhhh/hotclip/releases/tag/v0.20.0)** (2026-08-30) "Keep the subject in frame, keep the camera calm": **comfort-first vertical composition** (all visible face envelopes are fused per shot; lock the camera whenever one moving subject or a group fits safely, follow only when framing truly requires it); **centre snap** (near-centred source composition stays centred instead of gaining artificial drift); **lost-subject recovery** (hold through brief detector flicker, then ease back to centre after 1.25 seconds; a new shot without reliable faces centres immediately); **end-to-end receipt** (`clips.json` records total, locked, group-locked, tracked, recovery and centered-fallback shots, aggregated across stitched pieces). No new model or installer weight; sparse detection still falls back safely to centre crop.
**[v0.19.0](https://github.com/xixihhhh/hotclip/releases/tag/v0.19.0)** (2026-08-28) "Analyze once, make every next cut faster and sharper": **local multimodal evidence index** (source fingerprint + capability version + model identity, atomic writes, corrupt-entry invalidation and 64MB LRU bound); **nine-channel evidence chain** (model-free motion peaks join transcript, loudness, shots, facial emotion, vision, live chat, vocal tone and laughter/applause); **visible motion evidence** (a workbench timeline curve plus representative frames with reserved full-source coverage); **cross-entry reuse** (Tier-0 signals, TransNetV2 boundaries and optional VLM scans shared by desktop, CLI, MCP, folder watch/webhooks, with automatic rebuild after model/detector changes and no API key persistence); **independent diagnostics and cleanup** (analysis evidence never deletes render or transcript cache, and is always regenerable)
**[v0.18.0](https://github.com/xixihhhh/hotclip/releases/tag/v0.18.0)** (2026-08-28) "Quality you can inspect, upgrades you can measure": **word timing provenance** (native / second-pass aligned / interpolated / edited / estimated, legacy-safe); **focused review** (estimated-timing badges and filter in the transcript, timing receipt in candidate details); **localized alignment reports** (coverage, aligned/interpolated counts and uncertain spans in `clips.json`); **caption quality gate** (invalid timing, overlap, reading speed, flashes, oversize tokens and estimated ranges checked on the final rendered timeline); **repeatable golden evaluation** (local CER/WER, boundary error and highlight recall@K without new model downloads); plus a standalone `dev:web` browser preview for UI regression without the Electron runtime
**[v0.17.0](https://github.com/xixihhhh/hotclip/releases/tag/v0.17.0)** (2026-08-25) "Long videos get faster on repeat": **bounded base-render cache** (exact reuse across matching source/cuts/captions/reframe/audio/brand inputs, atomic writes, corrupt-entry invalidation and LRU pruning capped at 1GB); **safe smart copy** (H.264 video stream copy only for keyframe-aligned, pixel-unchanged continuous cuts; AAC, edge fades, denoise, loudness and sensitive-term muting remain active; every uncertainty or failure falls back to accurate encoding); **shared everywhere** (desktop exports, folder watch/webhooks, CLI and MCP use the same cache); **diagnostics and scoped cleanup** (bilingual size visibility and two-step cleanup that never touches projects, source media, models or transcript cache)
**[v0.16.0](https://github.com/xixihhhh/hotclip/releases/tag/v0.16.0)** (2026-08-25) "Projects persist, every edit can step back": **project workspace** (multi-project list, switch, rename, close, delete and media relinking; offline/changed sources keep their project; legacy sessions migrate automatically); **reversible editing history** (selection, copy/boundaries, manual clips and transcript corrections share undo/redo, capped at 60 commands / 4 MB and restored with the project); **professional keyboard controls** (transport, seek, in/out and candidate navigation with safe input/modal guards); **local A/B experiment center** (multi-version exports group per platform, metrics join through stable content IDs, same-platform/72-hour/minimum-sample gates, directional evidence only)
**[v0.15.1](https://github.com/xixihhhh/hotclip/releases/tag/v0.15.1)** (2026-08-24) "Work survives, publishing teaches": **hardware-accelerated export** (VideoToolbox / NVENC / QSV with transparent x264 fallback); **post-performance center** (import platform metrics and feed winner/laggard patterns back into selection); **verified public-video URL import** (Bilibili / YouTube-style links with checked resolver bootstrap and resume); **restart-safe editing** (source, transcript, candidates, selections and manual cuts recover); **durable automation task center** (one folder-watch/webhook queue with history, cancel, retry and interrupted state, never stored credentials); **transcript-timed sensitive-term muting** (correct through jump cuts and multi-piece clips, original captions retained); **publishing feedback ledger** (stable content IDs, prefilled metrics CSV, conservative matching and awaiting status); **desktop health diagnostics** (tools, nine model roles, LLM, disk/cache, cancellable/resumable core-model preparation); **topic-series packs** (meaningful repeated keywords become ordered episodes, variants excluded, manifests included)
**[v0.15.0](https://github.com/xixihhhh/hotclip/releases/tag/v0.15.0)** (2026-08-20) "The wizard retires, the workbench clocks in": **three-pane workbench** (the 3-step wizard retires — sources and recorder watch live on the left; source view + live 9:16 crop + timeline + a dense candidate table in the center; candidate details and detection tuning on the right; everything on one screen); **the timeline lands** (full-stream loudness curve + chat-heat curve + filmstrip thumbnails, candidate segments drawn right on the curves — where the highlights sit is visible at a glance); **candidates survive navigation** (a session store keeps candidates and review state across page switches); **explicit re-detect** (tuning detection params no longer silently re-runs the whole pass — you hit "Re-detect" when ready); **export schemes** (33 export toggles folded into six groups with three one-click schemes: Default / Selling bundle / Minimal & fast); **settings center** (seven scattered config spots — AI model / ASR engine / export & storage / brand style / glossary / recorder watch / language — merged into one page); **chat votes, counted properly** — Douyin recorder chat-log support (.jsonl auto-discovered alongside BililiveRecorder .xml, so Douyin streamers' replays finally get chat evidence too), interaction-event weighting (superchats / memberships / gifts / follows / likes on their own tiers — money and action votes beat plain messages), anti-spam caps (one sender's per-window contribution is capped), surge bonus (jumps over the previous window score extra — highlights explode, they don't simmer), fusion upgrades (multi-signal resonance bonus + content-adaptive windows), chat-guided sampling (expensive models spend their budget where the chat explodes); also fixes the real-machine preview black screen (multiple video elements loading one local-stream URL collide in Chromium) and filmstrip thumbnails blocked by CSP
Release history (v0.4.3 → v0.14.1) and milestones
- **[v0.14.1](https://github.com/xixihhhh/hotclip/releases/tag/v0.14.1)** (2026-08-11) "Think deep, still deliver": fixes "empty LLM response" ([#8](https://github.com/xixihhhh/hotclip/issues/8)) — reasoning models burn the whole 4,000-token output budget thinking and return no content; thinking-only responses now auto-retry once at 16,000 tokens, content misplaced into the `reasoning` field is recovered, and remaining failures are attributed with a next step (budget burned / content filter / transient empty response)
- **[v0.14.0](https://github.com/xixihhhh/hotclip/releases/tag/v0.14.0)** (2026-08-09) "Ship it, survive it": **transform score** (everything an export actually changed rolls into one score, previewed live, yellow card under 40 — pixel-level reposting is 2026's #1 takedown cause); **two-tier AI covers** (big-type vertical covers from clip titles: Seedream volume ~$0.04 / Nano Banana Pro premium $0.14, reusing the Atlas key); **AI BGM** (copyright-safe instrumental per stream genre, auto-wired into the BGM mix chain); **JianYing draft export** (per-clip draft folders with every AI cut on the timeline); **speaker-tag captions** (colored "A:"/"B:" prefixes); **utility-density boost** (step/list/number-dense clips flagged save-worthy to ride the 7-day slow push); **distribution ledger & evidence pack** (source-range CSV + ±3min source archive); **AIGC labeling helper** (per-platform label copy; cap hint over 5 clips per stream); **anti-fingerprint variants** (flash-forward opening on the last variant + seeded template jitter); **keep breaths** (optional 0.25s pauses in jump cuts); experimental **Linux AppImage** ([#7](https://github.com/xixihhhh/hotclip/issues/7))
- **[v0.13.0](https://github.com/xixihhhh/hotclip/releases/tag/v0.13.0)** (2026-08-09) "Watch it all, dare to drop": **three-tier quality gate** (zero-context verdict publish/review/drop + rule layer for hard flaws; drops fold away rescuable, unattended mode ships publish-tier only); **full-stream visual scan** (1 frame per 30s across the whole stream feeds on-screen events into evidence; free locally, cents per stream on cloud); **user brief** (plain words for what to hunt and what to skip); **streamer clip commands** ("clip that" = strongest evidence); **selling three-act stitch** (pain→demo→price auto-stitched); **transcript pick** (click sentences into clips: search / speaker filter / cross-segment); **LLM preflight** (doomed configs blocked with next steps, [#6](https://github.com/xixihhhh/hotclip/issues/6))
- **[v0.12.0](https://github.com/xixihhhh/hotclip/releases/tag/v0.12.0)** (2026-08-05) "Pick sharper, open louder": **flash-forward cold opens** (flash the most explosive 0.3-1s, then cut back; auto-coordinates with climax-first); **AI visual review** (contact-sheet look-over of top candidates: visual score feeds ranking, mismatches get flagged; free locally, API key switches to cloud); **precision cut points** (Paraformer second-pass word timestamps ±50ms fix captions/jump cuts/boundaries, safe fallback); **hook payoff check** (promised numbers must appear in the clip); **caption modernization** (keyword-highlight default, word-pop with per-word lighting and damped entrance); plus four never-wired export toggles fixed
- **[v0.11.0](https://github.com/xixihhhh/hotclip/releases/tag/v0.11.0)** (2026-08-05) "Ready to post": **platform publish packs** (per-platform folders after export: hard-linked video + covers re-cropped per platform aspect + copy trimmed to platform limits, with an adaptation manifest); **multi-version variants** (2-3 genuinely different packagings per clip: hook-angle title cards, teasers, copy and covers; tagged `variantOf`, compilations/EDL include originals only); **SFX cues & BGM** (whoosh on hard cuts, ding on the emotional peak, soft pop under the hook, ≤3 per clip; BGM loops with voice ducking and end fade, mixed in a separate zero-quality-loss pass); plus the **dynamic minimal** caption style
- **[v0.10.1](https://github.com/xixihhhh/hotclip/releases/tag/v0.10.1)** (2026-08-05) "Switchable models, tolerant of hiccups": **the model picker is now always reachable** — previously, once configured, there was no way to change provider or model at all (the panel only reappeared on a detection error), so v0.10.0's seven new providers were unreachable for existing users; a toolbar button now shows the current model and reopens the panel, and confirming after a change re-runs detection; **malformed LLM JSON retried once** (mainstream endpoints intermittently emit junk tokens mid-JSON, killing the whole run); **the signal path nominates fewer moments** (12 candidates made the model return an unfilled template; capped at 8)
- **[v0.10.0](https://github.com/xixihhhh/hotclip/releases/tag/v0.10.0)** (2026-08-05) "Pick better": a rework of **what gets picked** — clips can now be **stitched from multiple parts** (placing two moments ten minutes apart side by side is what makes a "caught contradicting himself" clip work at all); **stream-genre criteria** rebuilt against the **real category taxonomies** of Bilibili/Douyin (adding VTuber, radio, pets, food, esports, crafts and co-watching, which were missing entirely — and co-watching now explicitly forbids clipping the copyrighted content on screen); a new **signal-driven candidate path** so dance/pet/outdoor streams, whose transcripts are empty and which previously yielded nothing at all, get located by audio and visual signals instead; laughter is no longer treated as the highlight itself (it lags the punchline that caused it). Also: **vocal-tone and laughter/applause** as two new evidence paths, **auto-zoom**, **retake cutting**, **recorder webhooks** (BililiveRecorder/blrec), **multi-provider LLM presets** (DeepSeek, Model Studio, GLM, Kimi, SiliconFlow, OpenRouter, OpenAI) and **one-click model-list fetch** (model ids rot as vendors ship new generations — ask the endpoint instead)
- **[v0.9.4](https://github.com/xixihhhh/hotclip/releases/tag/v0.9.4)** (2026-07-31) "Chinese usernames are off the hook": fixes guaranteed transcription failure under non-ASCII Windows usernames ([#4](https://github.com/xixihhhh/hotclip/issues/4)) — model paths auto-convert to 8.3 short paths, audio samples read app-side; cross-drive model moves unblocked; model-load failures now say what to actually do
- **[v0.9.3](https://github.com/xixihhhh/hotclip/releases/tag/v0.9.3)** (2026-07-28) "You decide where things live": Settings page ([#3](https://github.com/xixihhhh/hotclip/issues/3)) — model storage visible & movable, three export quality tiers (Compact 66% smaller), default caption style & export location
- **[v0.9.2](https://github.com/xixihhhh/hotclip/releases/tag/v0.9.2)** (2026-07-27) "Honest errors, unsquashed UI": transcription failures attributed correctly ([#2](https://github.com/xixihhhh/hotclip/issues/2)); export-options bar wraps instead of bursting the layout; configurable output folder
- **[v0.9.1](https://github.com/xixihhhh/hotclip/releases/tag/v0.9.1)** (2026-07-24) "Windows first-run fix": the 100%-then-restart model download loop fixed (pure-JS extractor fallback for bzip2); extraction progress stage; atomic staging
- **[v0.9.0](https://github.com/xixihhhh/hotclip/releases/tag/v0.9.0)** (2026-07-24) "Learns your taste": review feedback loop + `doctor` self-check + resumable model downloads + structured post-copy templates (8 angles × 5 CTAs) + reference-clip entrance completed
- **[v0.8.0](https://github.com/xixihhhh/hotclip/releases/tag/v0.8.0)** (2026-07-20) "Clip like the viral one": reference-clip driven detection + self-repairing QA loop + banned-words lint (120+ rules) + Hormozi captions + contact-sheet frame scoring
- **[v0.7.0](https://github.com/xixihhhh/hotclip/releases/tag/v0.7.0)** (2026-07-16) "Self-check every cut": render QA + headless CLI & agent skill + compilation + cold-open + dual-aspect + product mode
- **[v0.6.0](https://github.com/xixihhhh/hotclip/releases/tag/v0.6.0)** (2026-07-10) "See the picture": six-signal evidence chain + bilingual captions + local MCP server + watch folder + publish kit
- **[v0.5.0](https://github.com/xixihhhh/hotclip/releases/tag/v0.5.0)** (2026-07-09) "Pick right, ship steady": review workbench + shot snapping + brand templates + two-stage funnel
- **[v0.4.3](https://github.com/xixihhhh/hotclip/releases/tag/v0.4.3)** (2026-07-06) Engineering base: transcript cache + clips.json receipt
| Milestone | Status |
|---|---|
| Desktop app · three local ASR tiers · AI highlights · vertical clips with captions · comfort-first composition | ✅ Done |
| Diarization · bubble captions · jump cuts · hands-off mode · installers | ✅ Done |
| v0.5 – v0.9 (workbench · MCP · watch folder · QA/repair · feedback loop · settings) | ✅ Shipped |
| v0.10 – v0.14 (multi-part stitching · genre criteria · quality gate · publish packs · variants · JianYing drafts · transform score · AI covers/BGM) | ✅ Shipped |
| v0.15 (three-pane workbench · timeline curves · chat interaction weighting) | ✅ Shipped |
| v0.15.1 (hardware export · URL import · recovery · durable queue · publishing feedback · diagnostics · topic series) | ✅ Shipped |
| v0.16 (project workspace · reversible editing · pro shortcuts · local A/B experiments) | ✅ Shipped |
| v0.17 (bounded render cache · keyframe-safe copy · shared across entry points · scoped cleanup) | ✅ Shipped |
| v0.18 – v0.27 (quality evaluation · caption quality gate · multimodal/on-screen-text evidence reuse · comfort-first reframing · render QA · adaptive picture finish · HDR-safe SDR export · selected-stream parity · quality covers · speech-safe cuts · smart 48k dialogue enhancement) | ✅ Shipped |
| English ASR upgrade (Parakeet) · code signing · deeper unattended mode | 🗺️ [Planned](docs/PRODUCT-PLAN.md) |
Full history in [Releases](https://github.com/xixihhhh/hotclip/releases) · Want a say in what ships first? [Discussions](https://github.com/xixihhhh/hotclip/discussions)
## FAQ
**What is the best free Opus Clip alternative without watermark?**
HotClip — free, open source (AGPL-3.0), runs locally on Windows/macOS/Linux (experimental), no watermark, no credits, no length caps. Optional cloud LLMs bill your own key; a local Ollama model makes it fully free and offline.
**Is there an AI clipper that runs locally without uploading my video?**
Yes — transcription, captions, cutting and export all run on your machine. Only the highlight-detection step calls a cloud LLM by default (your key, transcript text only); point it at local Ollama for a 100% offline pipeline.
**How do I turn a podcast or livestream replay into shorts?**
Import the file → the AI transcribes and flags highlights (fully editable) → export vertical 9:16 clips with captions, covers and post copy.
**How do I add animated word-by-word captions to a video?**
They're automatic — word-level timestamps drive dynamic captions burned into every clip (keyword highlight, word pop, bubble and more, one toggle to switch); SRT export and bilingual captions are one toggle away.
**Can it remove filler words and silences?**
Yes — silence jump cuts plus an um/uh filler pass, with caption timing remapped and every edit logged to clips.json.
**How does HotClip handle HDR video?**
PQ/HLG is tone-mapped to tagged SDR BT.709 only when primaries, colour matrix and range are complete and supported. Incomplete or unsupported HDR tags keep the existing render path, skip SDR-domain adaptive finishing and mark the result as unconverted instead of guessing; SDR and unknown transfers keep their existing path. No model, download or upload is added.
**Can live-chat data help pick highlights?**
Yes — and it's the strongest evidence there is. HotClip auto-discovers the chat file sitting next to a recording (BililiveRecorder .xml and Douyin-recorder .jsonl both work); chat density plus superchats, memberships, gifts, follows and like bursts feed straight into highlight detection, with per-sender spam caps and surge bonuses. No chat file? Loudness, shot cuts, motion, facial emotion, vocal tone and laughter signals cover for it.
**Does it work for Chinese video?**
Yes, exceptionally well — dedicated Chinese ASR engines (SenseVoice / Paraformer / FireRedASR2) cover dialects, Cantonese and code-switching; UI, captions and prompts are language-routed.
**Do I need a GPU?**
No. The local ASR models are int8-quantized and run fine on CPU; the highlight LLM runs in the cloud (or your local Ollama).
**First run: the speech-model download hits 100%, restarts from zero, and keeps downloading forever?**
Upgrade to [v0.9.1](https://github.com/xixihhhh/hotclip/releases) or newer — the Windows extraction bug is fixed, and previously downloaded bytes resume automatically.
## Developers
```bash
git clone https://github.com/xixihhhh/hotclip.git
cd hotclip
pnpm install
pnpm dev # run the desktop app in dev mode
pnpm test # run unit tests
```
**Tech stack**: Electron + React 19 + TypeScript + Tailwind 4 · ffmpeg (bundled) · sherpa-onnx local ASR + speaker diarization · libass dynamic captions + offscreen-Chromium bubble caption engine · LLM highlight detection (Atlas Cloud / Ollama / any OpenAI-compatible endpoint, BYO key)
Standing on the shoulders of
| Project | Role in HotClip |
|---|---|
| [sherpa-onnx](https://github.com/k2-fsa/sherpa-onnx) | Local speech recognition runtime (CPU-only friendly) |
| [SenseVoice](https://github.com/FunAudioLLM/SenseVoice) / [FunASR](https://github.com/modelscope/FunASR) | Fast 5-language ASR / Paraformer Chinese ASR & punctuation |
| [FireRedASR](https://github.com/FireRedTeam/FireRedASR) | Highest-accuracy tier: Mandarin, dialects, code-switching |
| [pyannote-audio](https://github.com/pyannote/pyannote-audio) + [3D-Speaker](https://github.com/modelscope/3D-Speaker) | Speaker diarization (local, zero upload) |
| [FFmpeg](https://ffmpeg.org/) + [libass](https://github.com/libass/libass) | Frame-accurate cutting / caption burn-in |
| [onnxruntime](https://github.com/microsoft/onnxruntime) | On-device model inference |
## License & boundaries
- Code: **AGPL-3.0-only**
- HotClip is for **your own content** or **clips you're authorized to make** (e.g. streamer clipping programs). Unauthorized re-uploading of movies/streams is not supported and not welcome.
## Community & related projects
- 🐛 [Report a bug / installation help](https://github.com/xixihhhh/hotclip/issues) · 💡 [Feature ideas & roadmap](https://github.com/xixihhhh/hotclip/discussions)
- 🔨 **[ClipForge](https://github.com/xixihhhh/clipforge)** — open-source AI e-commerce short-video generator: one product photo in, a ready-to-post shoppable video out. **HotClip clips highlights out of long videos; ClipForge builds short videos from a single image** — they pair well.
[](https://star-history.com/#xixihhhh/hotclip&Date)
**⭐ Star + Watch to catch new releases first.**
 # HotClip — Free Open-Source AI Video Clipper: Long Videos → Viral Vertical Shorts
**A free, local Opus Clip alternative — no credits, no watermark, no uploads**
[简体中文](README.md) | **English** | [Website](https://xixihhhh.github.io/hotclip/en.html) | [Download](https://github.com/xixihhhh/hotclip/releases/latest) | [FAQ](#faq) | [Issues](https://github.com/xixihhhh/hotclip/issues)